
cla
A quadratic programming solver answers one question at a time: the best portfolio for this
target return, or this risk aversion. Markowitz’s Critical Line Algorithm (1956) answers
all of them at once. It computes the entire efficient frontier of a portfolio with bounded
weights, exactly, in a finite number of steps, and it was designed for this problem and no
other. Bailey and López de Prado (2013) published the open implementation this module
follows, and AFML’s Chapter 16 uses CLA as the mean-variance benchmark against which
hrp is judged.
The idea
Section titled “The idea”Fix which assets sit at a bound and which are free. Among the free assets the optimal weights are a linear function of the risk-aversion parameter , so as falls from infinity to zero the optimal portfolio moves along a straight line in weight space, the critical line, until some asset hits a bound or some bounded asset wants to leave one. That portfolio is a turning point. The free set changes by one asset, and a new line begins.
The frontier is therefore piecewise: between two consecutive turning points every efficient portfolio is a convex combination of them. The algorithm starts at the maximum-return portfolio, , and walks down to the minimum-variance portfolio, , solving a small linear system at each step. A handful of turning points describes the whole frontier exactly.
What allocate returns
Section titled “What allocate returns”CLA::allocate(prices, expected_returns, covariance, resample_by, solution) takes either a
price history or and directly, and one of four solution names:
solution | weights holds |
|---|---|
"cla_turning_points" (default) | every turning point, from maximum return to minimum variance |
"min_volatility" | the one turning point with the least variance |
"max_sharpe" | the frontier portfolio with the highest ratio of return to volatility |
"efficient_frontier" | about 100 portfolios spread along the segments, with efficient_frontier_means and efficient_frontier_sigma filled in |
lambdas, gammas and free_weights always describe the turning points, whichever solution
was asked for. Bounds are a WeightBounds::Tuple(lo, hi) for all assets or
WeightBounds::Lists(lows, highs) per asset; from Python, weight_bounds_lower and
weight_bounds_upper.
from openquant import cla, portfolio
# The four assets of the portfolio_optimization page.names = ["bonds", "equity", "small cap", "gold"]mu = [0.03, 0.07, 0.09, 0.04]vol = [0.05, 0.16, 0.22, 0.15]rho = [[1.0, 0.1, 0.1, 0.1], [0.1, 1.0, 0.8, 0.0], [0.1, 0.8, 1.0, 0.0], [0.1, 0.0, 0.0, 1.0]]cov = [[rho[i][j] * vol[i] * vol[j] for j in range(4)] for i in range(4)]
def stats(w):    ret = sum(a * b for a, b in zip(w, mu))    risk = sum(w[i] * cov[i][j] * w[j] for i in range(4) for j in range(4)) ** 0.5    return ret, risk
points = cla.allocate_cla(expected_returns=mu, covariance_matrix=cov)print("turning point       " + "  ".join(f"{n[:5]:>5s}" for n in names) + "   return    risk")for k, w in enumerate(points["weights"]):    ret, risk = stats(w)    print(f"{k:13d}       " + "  ".join(f"{round(x, 2) + 0.0:5.2f}" for x in w) + f"   {ret:6.3f}  {risk:6.3f}")
by_cla = cla.allocate_cla(expected_returns=mu, covariance_matrix=cov, solution="max_sharpe")["weights"][0]by_qp = portfolio.allocate_from_inputs(mu, cov, "max_sharpe")[0]gap = max(abs(a - b) for a, b in zip(by_cla, by_qp))print("max Sharpe: CLA and the QP solver agree to 1e-8:", gap < 1e-8)
turning point bonds equit small gold return risk 0 0.00 0.00 1.00 0.00 0.090 0.220 1 0.00 0.00 1.00 0.00 0.090 0.220 2 0.00 0.09 0.91 0.00 0.088 0.212 3 0.00 0.31 0.44 0.25 0.071 0.144 4 0.82 0.10 0.00 0.08 0.035 0.048 5 0.87 0.06 0.00 0.07 0.033 0.048max Sharpe: CLA and the QP solver agree to 1e-8: TrueRead the table as a story of assets entering. The frontier starts fully in small cap, the highest-return asset. Equity enters at point 2, gold at point 3, and bonds at point 4, by which time small cap has been driven to zero and leaves. Point 5 is the minimum-variance portfolio. Any efficient portfolio is a blend of two neighbouring rows: one returning 5% is part of the way from row 3 to row 4.
The last line is an independent check. portfolio_optimization
reaches its answers by an iterative solver and this module by linear algebra along the
critical line, and on the same inputs they agree to better than one part in a hundred million.
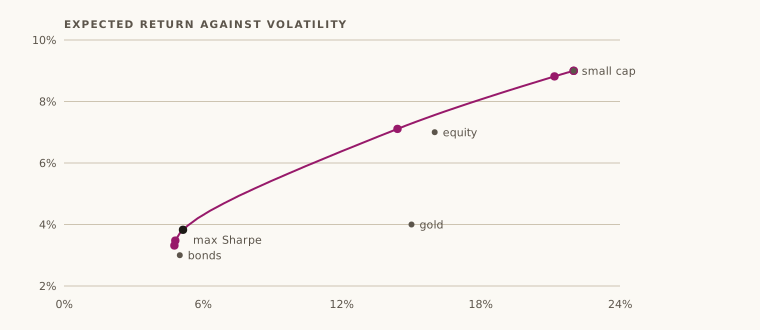
"efficient_frontier" solution, with its turning points. Single assets other than the highest-returning one lie inside it.From Rust
Section titled “From Rust”use nalgebra::DMatrix;use openquant::cla::{ClaError, WeightBounds, CLA};
let mu = DMatrix::from_column_slice(4, 1, &[0.03, 0.07, 0.09, 0.04]);let vol = [0.05, 0.16, 0.22, 0.15];let rho = [[1.0, 0.1, 0.1, 0.1], [0.1, 1.0, 0.8, 0.0], [0.1, 0.8, 1.0, 0.0], [0.1, 0.0, 0.0, 1.0]];let cov = DMatrix::from_fn(4, 4, |i, j| rho[i][j] * vol[i] * vol[j]);
let mut cla = CLA::new(WeightBounds::Tuple(0.0, 1.0), "mean");cla.allocate(None, Some(&mu), Some(&cov), None, None)?;
// The walk starts at the highest-return asset and ends at minimum variance, where lambda is 0.assert_eq!(cla.weights.first().unwrap(), &vec![0.0, 0.0, 1.0, 0.0]);assert_eq!(*cla.lambdas.last().unwrap(), 0.0);// Every turning point is a feasible portfolio.for w in &cla.weights { assert!((w.iter().sum::<f64>() - 1.0).abs() < 1e-9); assert!(w.iter().all(|x| (-1e-9..=1.0 + 1e-9).contains(x)));}
// With a 40% cap the frontier starts from the best feasible corner instead.let mut capped = CLA::new(WeightBounds::Tuple(0.0, 0.4), "mean");capped.allocate(None, Some(&mu), Some(&cov), None, Some("min_volatility"))?;assert!(capped.weights[0].iter().all(|x| *x <= 0.4 + 1e-9));
assert!(matches!( cla.allocate(None, Some(&mu), Some(&cov), None, Some("max_return")), Err(ClaError::UnknownSolution(_))));What to watch for
Section titled “What to watch for”- From prices, CLA uses simple returns, as do
portfolio_optimization,hrpandhcaa. Its expected returns are annualised and its covariance is left per period, which moves no turning point. From the same prices, or the same and , CLA andportfolio_optimizationfind the same maximum-Sharpe portfolio; until #110 was fixed,portfolio_optimizationtook log returns and the two differed. "max_sharpe"has no risk-free rate. It maximises , the tangency portfolio for a rate of zero, which for low-yielding safe assets lands near the minimum-variance end, as in the figure. For a non-zero rate, subtract it from the expected returns before calling, or useportfolio_optimization.- The first turning point appears twice. The walk records its starting portfolio and then
the first turning point proper, which is the same portfolio with a finite ; the
first
lambdais infinite. Skip index 0 when plotting against . - Errors name their cause. Bounds with no feasible portfolio (a bound that is not
finite, a lower bound above its upper bound, lower bounds summing to more than 1, upper
bounds to less than 1) return
InfeasibleBounds; a covariance that cannot be inverted among the free assets returnsSingularCovariance; a walk that does not reach returnsNoTermination; anAssetPricesindex without one date per row returnsInvalidPriceIndex. Python raisesValueErrorwith the same messages. Before #168 the first was reported asDimensionMismatchand the next three asInvalidAssetPrices, which no longer exists. A lower bound above its upper bound was not caught at all: every turning point was then purged, and"max_sharpe"panicked on the empty frontier.NoTurningPointsis now returned if that ever happens. - It is exact, and it inherits every weakness of its inputs. CLA removes solver error, not estimation error. The frontier’s upper end is always the single asset with the highest expected return, whatever its risk, and small changes in move the turning points a long way; see Markowitz’s curse.
- The covariance matrix must be positive definite among the free assets. With more
assets than observations it is singular and the linear systems along the line fail. Shrink
it first, or use
hrp, which does not invert anything. resample_byis positional — every 5th or 21st row — and produced scrambled matrices before #93 was fixed.- Methods beginning with an underscore are public for testing parity with the reference
implementation, not for use.
_purge_num_errand_purge_excessare already called byallocate.
Related modules
Section titled “Related modules”portfolio-optimization— single portfolios by quadratic programming, with a risk-free rate and per-asset bounds by index.hrp,hcaa— what AFML proposes instead.risk-metrics— variance and tail risk of a chosen portfolio.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.cla.
cla.allocate_cla— Critical Line Algorithm portfolios (Markowitz; Bailey and López de Prado, 2013; AFML chapter 16).
Rustdoc for this commit, with every public item of openquant::cla (after a crates.io release the same pages are on docs.rs):