
sampling
A triple-barrier label is a statement about a stretch of prices, from the event bar to the
bar where a barrier was touched. Two labels whose stretches overlap are statements about some
of the same returns, so they are not independent observations — and most of machine learning,
from the bootstrap inside a random forest to the standard error of a cross-validation score,
assumes they are (AFML §4.2). This module measures the overlap and provides a bootstrap that
draws around it. sample-weights turns the same measurement into
weights.
Everything here works in bar positions, not timestamps: a label is a pair
(start, end) of inclusive indices into the bar series.
Concurrency and uniqueness
Section titled “Concurrency and uniqueness”Let be 1 when label spans bar . The number of labels alive at bar is , and the uniqueness of label at that bar is : a label that shares a bar with one other owns half of it. The average uniqueness of a label is that quantity averaged over its own lifespan,
which is 1 for a label that overlaps nothing and falls toward for a label that shares every bar with others.
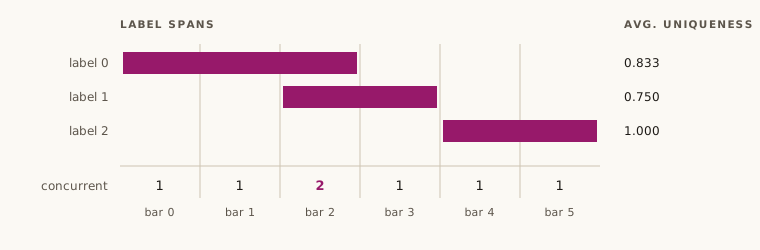
The example is the one AFML works by hand in §4.5.3: three labels over six bars.
from openquant import sampling
spans = [(0, 2), (2, 3), (4, 5)]  # (first bar, last bar) of each label, inclusiveind = sampling.get_ind_matrix(spans, list(range(6)))for bar, row in enumerate(ind):    print(f"bar {bar}: {row}  concurrent = {sum(row)}")
print("average uniqueness per label:",      [round(u, 3) for u in sampling.get_av_uniqueness_from_triple_barrier(spans, 6)])
# Sequential bootstrap, second draw, given that label 1 was drawn first.concurrency = [float(row[1]) for row in ind]u = sampling.bootstrap_loop_run(ind, concurrency)print("after drawing label 1:", [f"{v / sum(u):.3f}" for v in u])
bar 0: [1, 0, 0] concurrent = 1bar 1: [1, 0, 0] concurrent = 1bar 2: [1, 1, 0] concurrent = 2bar 3: [0, 1, 0] concurrent = 1bar 4: [0, 0, 1] concurrent = 1bar 5: [0, 0, 1] concurrent = 1average uniqueness per label: [0.833, 0.75, 1.0]after drawing label 1: ['0.357', '0.214', '0.429']Labels 0 and 1 meet at bar 2. Label 0 owns two of its three bars outright and half of the third, ; label 1 owns one and a half of two, . The last line is the book’s .
get_ind_matrix(label_endtime, bar_index) returns the matrix itself, one row per bar and one
column per label. get_ind_mat_label_uniqueness returns for every bar and label,
get_ind_mat_average_uniqueness the mean of over labels as a single number, and
num_concurrent_events(n_bars, spans, _) just .
The sequential bootstrap
Section titled “The sequential bootstrap”A standard bootstrap draws labels uniformly with replacement. When labels overlap, that sample is more redundant than it looks: the in-bag observations resemble each other, and the out-of-bag ones resemble the in-bag ones, so bagged trees are more correlated and out-of-bag accuracy is inflated (§4.5).
The sequential bootstrap (§4.5.1–2) draws one label at a time and, before each draw, lowers the probability of every label that overlaps what has already been drawn. With the draws so far, the probability of drawing next is proportional to the average uniqueness would have if it were added:
bootstrap_loop_run(ind_mat, concurrency) computes the for one step,
given the per-bar concurrency of the draws so far; seq_bootstrap(ind_mat, sample_length, warmup_samples) runs the whole loop and returns the drawn label indices. In the example
above, having drawn label 1, the label that does not touch it becomes twice as likely as
drawing label 1 again — but no probability goes to zero. Repeats remain possible, only less
likely.
How much does it buy? The measure is the average uniqueness of the drawn sample, computed on the indicator matrix restricted to the drawn columns, repeats included.
import random
from openquant import sampling
# 40 labels of 10 bars each, a new one every 3 bars: every label overlaps six others.n, length, step = 40, 10, 3spans = [(step * i, step * i + length - 1) for i in range(n)]ind = sampling.get_ind_matrix(spans, list(range(step * n + length)))
def sample_uniqueness(drawn):    return sampling.get_ind_mat_average_uniqueness([[row[c] for c in drawn] for row in ind])
rng, trials = random.Random(4), 200standard = sum(sample_uniqueness([rng.randrange(n) for _ in range(n)]) for _ in range(trials)) / trialssequential = sum(sample_uniqueness(sampling.seq_bootstrap(ind, random_state=s)) for s in range(trials)) / trialsprint(f"all {n} labels, each once: {sample_uniqueness(range(n)):.3f}")print(f"standard bootstrap:       {standard:.3f}")print(f"sequential bootstrap:     {sequential:.3f}")
all 40 labels, each once: 0.318standard bootstrap: 0.301sequential bootstrap: 0.312Read the three numbers together. Sequential sampling recovers most of what a uniform bootstrap loses to repeated and adjacent draws, but it cannot exceed what the label set allows: with every label overlapping six others, no sample of 40 is much more than 30% unique. AFML’s Monte Carlo (§4.5.4) reports a larger gap — median uniqueness of 0.6 against 0.7 — on random label sets with far less structural overlap. If average uniqueness is low, the first remedy is upstream: a wider CUSUM threshold or a shorter vertical barrier.
From Rust
Section titled “From Rust”use openquant::sampling::{ bootstrap_loop_run, get_av_uniqueness_from_triple_barrier, get_ind_matrix, seq_bootstrap,};
let spans = vec![(0, 2), (2, 3), (4, 5)];let bars: Vec<usize> = (0..6).collect();let ind = get_ind_matrix(&spans, &bars)?;assert_eq!(ind[2], vec![1, 1, 0]);
let uniqueness = get_av_uniqueness_from_triple_barrier(&spans, bars.len())?;assert!((uniqueness[0] - 5.0 / 6.0).abs() < 1e-12);
// Second-draw probabilities after label 1, as in AFML §4.5.3.let concurrency: Vec<f64> = ind.iter().map(|row| f64::from(row[1])).collect();let u = bootstrap_loop_run(&ind, &concurrency)?;let total: f64 = u.iter().sum();assert!((u[0] / total - 5.0 / 14.0).abs() < 1e-12);assert!((u[2] / total - 6.0 / 14.0).abs() < 1e-12);
// One label index per draw; `None` draws as many as there are labels.let drawn = seq_bootstrap(&ind, None, None)?;assert_eq!(drawn.len(), 3);assert!(drawn.iter().all(|&label| label < 3));A span whose start is after its end, a ragged matrix, a concurrency vector of the wrong
length and a warm-up index beyond the last label are each an InputError.
What to watch for
Section titled “What to watch for”seq_bootstrapis reproducible only with a seed. Withoutrandom_stateit draws from the thread-local generator, so repeated calls differ; from Rust,seq_bootstrap_with_rngtakes any generator.warmup_samplesforces the first draws and is consumed from the end of the list; every later draw is uniqueness-weighted.- The matrix is dense.
get_ind_matrixallocates bars × labels bytes andseq_bootstraprescans all of it for every draw, so a full-length sample costs on the order of bars × labels² operations. Ten thousand labels over a hundred thousand bars is a gigabyte and will not finish. Bootstrap within blocks, or drawsample_lengthwell below the label count. - Spans are inclusive bar positions. Convert event and barrier-touch timestamps to
positions in the same bar series before calling. An
endbeyond the last bar is not an error: bothnum_concurrent_eventsandget_ind_matrixtruncate the span silently. num_concurrent_eventsignores its third argument. It is kept for signature compatibility with Snippet 4.1; pass an empty list.- From Python, the matrix is a list of lists of 0/1 ints, one inner list per bar. Each cell is an eight-byte pointer where Rust stores one byte, so the density warning above bites sooner from Python.
- Uniqueness is not a weight yet. A sample weight also reflects how much happened during
the label; see
sample-weights.
Related modules
Section titled “Related modules”labeling— produces the event and barrier-touch times that become spans.sample-weights— weights from the same concurrency counts.sb-bagging— a bagging ensemble built onseq_bootstrap.cross-validation— purging and embargo, which deal with the same overlap across the train/test boundary.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.sampling.
sampling.get_ind_matrix— Indicator matrix of which labels span which bars (AFML Snippet 4.3).sampling.get_ind_mat_average_uniqueness— Mean over labels of each label's average uniqueness (AFML Snippet 4.4, whole sample).sampling.get_ind_mat_label_uniqueness— Per-bar uniqueness `u[t][i] = ind_mat[t][i] / c_t` of every label (AFML section 4.4).sampling.get_av_uniqueness_from_triple_barrier— Average uniqueness of each label over its lifespan, from label spans (AFML Snippet 4.4).sampling.num_concurrent_events— Number of labels alive at each bar, `c_t` (AFML Snippet 4.1).sampling.bootstrap_loop_run— One step of the sequential bootstrap (the inner loop of AFML Snippet 4.5).sampling.seq_bootstrap— Sequential bootstrap of label indices (AFML Snippet 4.5).
Rustdoc for this commit, with every public item of openquant::sampling (after a crates.io release the same pages are on docs.rs):