
cross_validation
k-fold cross-validation estimates out-of-sample performance on the assumption that a training observation tells the model nothing about a test observation beyond what the model generalises. With financial labels that assumption fails in a specific, mechanical way (AFML §7.3). A label formed at bar and resolved at bar is a function of the prices in between. If a training label’s span overlaps a test label’s span, the two share returns: the model has been shown part of the answer, and the fold’s score is inflated. Shuffling makes it worse, since it scatters such pairs across every fold boundary.
From Python, openquant.cross_validation returns the same splits as numpy index arrays, to
use with any model (see From Python).
Purging and embargo
Section titled “Purging and embargo”Purging (§7.4.1) removes from the training set every label whose span intersects the window the test labels cover. For a test fold that window runs from the first test label’s start to the latest end among the fold’s labels, which with variable-length labels need not be the last label’s. A training label is dropped if it starts inside the window, ends inside it, or envelops it.
Embargo (§7.4.2) removes a further stretch of training labels just after the test window, and nothing before it. Purging handles overlap in the labels; the embargo handles what leaks through the features, which are usually serially correlated — a moving average computed a few bars after the test window still contains test-window prices.
PurgedKFold::new(n_splits, samples_info_sets, pct_embargo) takes one (start, end) pair
per sample, in time order, and split(n_samples) returns (train_indices, test_indices) for
each fold. Folds are contiguous blocks; nothing is shuffled.
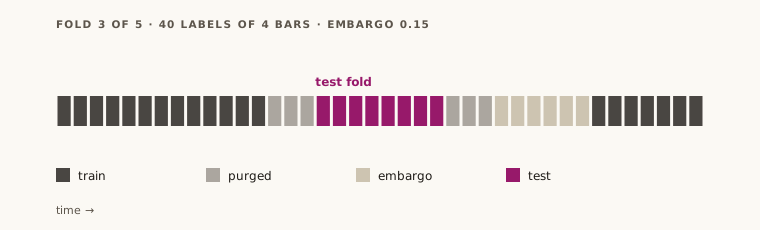
pct_embargo = 0.15. Twenty of the 32 non-test labels survive.Where the embargo starts
Section titled “Where the embargo starts”The embargo follows Snippet 7.3. It covers
samples, and it starts where the purge ends: at the first sample after the fold whose label
starts after the latest end among the fold’s labels (the book’s maxT1Idx). So counts
samples beyond the purge, and a short embargo still removes something when labels are long.
Only later features can contain test-window prices, so nothing before the fold is embargoed.
backtesting-engine uses the same code for its embargo, so
the two modules train on the same samples. Two details differ from the book’s code, and
neither loosens the split. Overlap is tested on closed intervals, so a label that ends
exactly when the fold starts is purged, where Snippet 7.3 keeps it. And is rounded up
rather than truncated, so any positive pct_embargo embargoes at least one sample.
Before #134, PurgedKFold embargoed
both sides of the fold and counted from the fold’s edges, not from the end of the purge.
The example: forty hourly labels, each resolved three hours after it starts, five folds, third fold.
use chrono::{Duration, NaiveDate};use openquant::cross_validation::{CrossValidationError, PurgedKFold};
let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let info_sets: Vec<_> =    (0..40).map(|i| (open + Duration::hours(i), open + Duration::hours(i + 3))).collect();
let train_of = |pct_embargo: f64| -> Result<Vec<usize>, CrossValidationError> {    Ok(PurgedKFold::new(5, info_sets.clone(), pct_embargo)?.split(40)?[2].0.clone())};
// Test fold is samples 16-23. Purging alone removes 13-15 and 24-26.assert_eq!(train_of(0.0)?, (0..=12).chain(27..=39).collect::<Vec<usize>>());// An embargo of ceil(0.07 * 40) = 3 samples starts where the purge ends: 27-29.assert_eq!(train_of(0.07)?, (0..=12).chain(30..=39).collect::<Vec<usize>>());// Six samples: 27-32. Nothing before the fold is embargoed.assert_eq!(train_of(0.15)?, (0..=12).chain(33..=39).collect::<Vec<usize>>());
embargo 0.00: test 16-23 train 0-12, 27-39 (26 of 32 kept)embargo 0.07: test 16-23 train 0-12, 30-39 (23 of 32 kept)embargo 0.15: test 16-23 train 0-12, 33-39 (20 of 32 kept)The text block is the output of cargo run --example docs_cross_validation, and
test_docs_page_example_values pins the same three index sets.
pct_embargo is a fraction of the whole sample count, rounded up: 0.01 on 5,000 samples
is 50 samples. AFML suggests a value around 0.01. new rejects values outside , and
information sets that end before they start.
Diagnostics and combinatorial splits
Section titled “Diagnostics and combinatorial splits”split_with_diagnostics(n_samples) returns the same folds as split, each as a
PurgedSplit whose diagnostics say why each excluded sample was excluded.
purged_indices overlap the test window. embargo_indices lie inside an embargo window,
whether or not they were also purged. The window starts after the purge, so in a k-fold split
no sample is both; in CPCV a window can reach into another test block’s purged zone, and those
samples are listed in both. test_ranges gives the test set as ranges.
Training is every sample in none of the three. overlap_count_after_purge counts training
labels that still intersect a test label. It is always 0, and is there so a pipeline can
assert it.
cpcv_splits(n_samples, k) is combinatorial purged CV (AFML §12.4). It returns one
CpcvSplit for each of the ways to test of the folds at once, in
lexicographic order of test_fold_ids. Adjacent test folds form one block, and each block is
purged and embargoed like a split fold, so k = 1 gives back split_with_diagnostics.
cpcv_paths(k) returns the backtest paths those splits
make. Path takes, for each fold, the -th split that tests it: split_for_fold[g] is that
split’s split_id. The numbering matches backtesting-engine’s
run_cpcv, which also scores returns along the paths.
naive_kfold_splits is the unpurged baseline §7.3 warns against, and
count_train_test_overlaps(info_sets, train, test) counts training samples whose span
intersects some test sample’s. Together they measure the leak that purging removes.
use chrono::{Duration, NaiveDate};use openquant::cross_validation::{count_train_test_overlaps, naive_kfold_splits, PurgedKFold};
let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let info_sets: Vec<_> =    (0..40).map(|i| (open + Duration::hours(i), open + Duration::hours(i + 3))).collect();let cv = PurgedKFold::new(5, info_sets.clone(), 0.15)?;
// The third fold of the example above, with the reason for each exclusion.let fold = &cv.split_with_diagnostics(40)?[2];assert_eq!(fold.diagnostics.test_ranges, vec![(16, 24)]);assert_eq!(fold.diagnostics.purged_indices, vec![13, 14, 15, 24, 25, 26]);// Six samples after the purged zone, none before the fold.assert_eq!(fold.diagnostics.embargo_indices, (27..=32).collect::<Vec<usize>>());
// N = 5, k = 2: C(5, 2) = 10 splits and 2/5 * 10 = 4 paths.assert_eq!(cv.cpcv_splits(40, 2)?.len(), 10);assert_eq!(cv.cpcv_paths(2)?.len(), 4);
// Unpurged, the same fold trains on 6 labels that overlap the test window.let (train, test) = &naive_kfold_splits(40, 5)?[2];assert_eq!(count_train_test_overlaps(&info_sets, train, test)?, 6);
Features with memory: a bias purging does not remove
Section titled “Features with memory: a bias purging does not remove”Purging and the embargo stop one leak: training labels that share returns with test labels, and training features computed from test-window prices. They do not change who the model for a middle fold is trained on. In every k-fold split but the last, and every CPCV split but the one that tests the last groups, that model is also fitted on samples from after the test fold. AFML §12.3 lists this among the pitfalls of cross-validation (the training set does not trail the testing set) and points to purging and the embargo (Chapter 7) as the remedy. For a feature with memory — the price level, a weakly differenced price, a long moving average — they are not enough, and scores come out above chance on data with no signal at all.
The mechanism, on a random walk with the log price as the only feature:
- Inside any window a random walk looks mean-reverting, so a model fitted on levels learns to bet against the level relative to its training mean. On 500-event random walks the fitted slope is negative in about nine middle folds of ten.
- For a middle fold, the training mean includes the levels after the fold. “Below the training mean” then tends to mean “the price goes on to rise”: betting up when the price is below the before-and-after training mean is right 54% of the time on the middle folds of pure random walks, and betting against the mean of the earlier samples alone is right 50% of the time.
- Purging finds nothing to remove: no training label overlaps a test label. The bias is in what the model learned from the later samples, not in shared returns.
Returns and other short-memory features carry little of this, so under k-fold or CPCV a
comparison of a level-like feature against returns is tilted toward the level. Runbook 14
(fracdiff features against returns, issue
#217) found it on random walks: purged
5-fold CV gave the log price an annualised net Sharpe ratio of 1.85 on the synthetic SYN_*
sample, and FFD features beat returns by 0.024 of AUC ( = 4.6) on 30 zero-signal paths.
Walk-forward removed the Sharpe-ratio bias.
Two defences, both in this module:
- Walk-forward over the same folds.
walk_forward_splits(n_samples, min_train_folds)tests the folds ofsplitfrommin_train_foldson, and trains each only on the samples before it, purged. No model sees a later sample. The embargo removes nothing here, because it only drops samples after a test block, and none of those train. Because the folds are the k-fold folds, a feature can be scored fold for fold under both schemes.backtesting-engine’srun_walk_forwardis the backtest-engine version, with its own block sizes. - A null through the same splits. Rebuild the data with no signal (simulate it, or draw
the demeaned returns with replacement), recompute features and labels from it, run it
through the same splits, and compare the real score with that distribution rather than
with chance. The Python helpers
null_score_distributionandbootstrap_returnsdo this. Two tempting nulls are wrong here. Permuting the labels alone keeps every feature but cuts the link between a label and the path the level records, which is what the bias uses, so it would pass a biased scheme. Shuffling the returns without replacement fixes their sum, so every shuffled path ends where the real one does: a random-walk bridge, which mean-reverts, and on which the level beats chance even walk-forward (0.517 in the example below, against 0.500 with the bootstrap).
use chrono::{Duration, NaiveDate};use openquant::cross_validation::PurgedKFold;
let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let info_sets: Vec<_> =    (0..40).map(|i| (open + Duration::hours(i), open + Duration::hours(i + 3))).collect();let cv = PurgedKFold::new(5, info_sets, 0.15)?;
// Folds 1 to 4 are tested, each trained only on what comes before it.let splits = cv.walk_forward_splits(40, 1)?;assert_eq!(splits.len(), 4);let wf = &splits[1];assert_eq!(wf.test_fold_id, 2);// The third fold (16-23) trains on 0-12: 13-15 are purged, and 24-39 are later.assert_eq!(wf.split.train_indices, (0..=12).collect::<Vec<usize>>());assert_eq!(wf.split.diagnostics.purged_indices, vec![13, 14, 15]);// The k-fold split of the same fold also trains on 33-39, after the test fold.assert_eq!(cv.split(40)?[2].0, (0..=12).chain(33..=39).collect::<Vec<usize>>());
The integration test level_feature_is_biased_under_purged_kfold_but_not_walk_forward runs a
one-feature logistic model on the level of 400 Gaussian random walks (500 events each, labels
the sign of the next five steps, pct_embargo = 0.01). Purged 5-fold CV scores an accuracy of
0.52, nine standard errors above chance; walk-forward over the same folds scores 0.50.
Pooled AUC is biased even walk-forward. Runbook 14 also saw level-like features ahead on out-of-fold AUC walk-forward. That is the metric, not a leak. AUC compares the scores of events at different times, and a later event’s score, computed from past prices only, already reflects an earlier event’s outcome. On random walks, a fixed score with no fitting at all, minus the deviation of the price from its past 100 bars’ mean, has a within-fold AUC of 0.54 on five-bar labels. The excess comes from pairs of events close in time: 0.89 over pairs within the label horizon, 0.65 over pairs 6 to 40 bars apart, and 0.50 over pairs 200 to 400 bars apart, where one event’s outcome no longer shows in the other’s score. Judge features with memory on a per-event measure — accuracy, log loss, net returns — against a null run through the same splits, not on pooled AUC.
Scoring
Section titled “Scoring”ml_cross_val_score(classifier, x, y, sample_weight, splits, scoring) fits on each training
set and scores each test set. It takes any SimpleClassifier — a two-method trait, fit
and predict_proba — and one of three Scoring rules:
Scoring | Value per fold |
|---|---|
Accuracy | share of test samples where proba ≥ 0.5 matches the label |
NegLogLoss | , with clipped to ; higher is better |
F1 | harmonic mean of precision and recall for the positive class; 0 when there are no positive predictions |
AFML’s advice (§7.5 and Chapter 9) is to prefer log loss for anything that will be sized by probability: accuracy scores a confident wrong call the same as a hesitant one, and bet sizing does not.
use chrono::{Duration, NaiveDate};use openquant::cross_validation::{ml_cross_val_score, PurgedKFold, Scoring, SimpleClassifier};
/// Predicts the training base rate, whatever the features. A floor for any real model.struct BaseRate(f64);
impl SimpleClassifier for BaseRate {    fn fit(&mut self, _x: &[Vec<f64>], y: &[f64], _sample_weight: Option<&[f64]>) {        self.0 = y.iter().sum::<f64>() / y.len() as f64;    }    fn predict_proba(&self, x: &[Vec<f64>]) -> Vec<f64> {        vec![self.0; x.len()]    }}
let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let info_sets: Vec<_> =    (0..40).map(|i| (open + Duration::hours(i), open + Duration::hours(i + 3))).collect();let x: Vec<Vec<f64>> = (0..40).map(|i| vec![f64::from(i)]).collect();let y: Vec<f64> = (0..40).map(|i| f64::from(u8::from(i % 4 == 0))).collect();
let splits = PurgedKFold::new(5, info_sets, 0.0)?.split(40)?;let scores = ml_cross_val_score(&mut BaseRate(0.0), &x, &y, None, &splits, Scoring::NegLogLoss)?;
// A quarter of labels are positive, so every fold scores near ln-loss of p = 0.25.let entropy = -(0.25 * 0.25f64.ln() + 0.75 * 0.75f64.ln());assert_eq!(scores.len(), 5);assert!(scores.iter().all(|s| (s + entropy).abs() < 0.002));
From Python
Section titled “From Python”openquant.cross_validation returns indices and fits nothing, so any model can use them.
t0 and t1 are required: t0[i] is when label starts and t1[i] when it resolves.
They can be numpy datetime64 arrays, pandas or polars datetime columns, datetime objects,
ISO strings, or plain integers such as bar positions. The splitting is the Rust code above.
| Function | Returns |
|---|---|
purged_kfold_splits(t0, t1, n_splits, pct_embargo) | [(train_idx, test_idx), ...], numpy int arrays |
split_with_diagnostics(t0, t1, n_splits, pct_embargo) | one dict per fold: the indices plus test_ranges, purged_indices, embargo_indices, overlap_count_after_purge |
cpcv_splits(t0, t1, n_splits, n_test_splits, pct_embargo) | the same dicts for the CPCV splits, with test_fold_ids |
cpcv_paths(n_splits, n_test_splits) | an (n_paths, n_splits) array: paths[p, g] is the split whose predictions path p uses for fold g |
walk_forward_splits(t0, t1, n_splits, pct_embargo, min_train_folds=1) | [(train_idx, test_idx), ...] for folds min_train_folds on, each trained only on earlier samples |
walk_forward_split_with_diagnostics(...) | the same as dicts, with test_fold_id and purged_indices |
null_score_distribution(evaluate, splits, make_null, n_null, seed) | n_null scores of evaluate(make_null(rng), splits): the pipeline on no-signal data, through the same splits |
bootstrap_returns(returns, demean=True) | a make_null that draws the (demeaned) returns i.i.d. with replacement: a driftless random walk |
null_p_value(observed, null) | , of the null scores at least observed |
naive_kfold_splits(n_samples, n_splits) | the unpurged baseline |
count_train_test_overlaps(t0, t1, train, test) | the number of leaking training samples |
import numpy as npfrom openquant import cross_validation as cv
# The example above: 40 hourly labels, each resolved 3 hours after it starts.t0 = np.datetime64("2024-01-02T09:00") + np.arange(40) * np.timedelta64(1, "h")t1 = t0 + np.timedelta64(3, "h")
train, test = cv.purged_kfold_splits(t0, t1, n_splits=5, pct_embargo=0.15)[2]print("test", test.min(), "-", test.max(), "train", train.tolist())
fold = cv.split_with_diagnostics(t0, t1, n_splits=5, pct_embargo=0.15)[2]print("purged", fold["purged_indices"].tolist())
splits = cv.cpcv_splits(t0, t1, n_splits=5, n_test_splits=2, pct_embargo=0.15)print(len(splits), "CPCV splits; split 1 tests folds", splits[1]["test_fold_ids"])print(cv.cpcv_paths(n_splits=5, n_test_splits=2))
naive_train, naive_test = cv.naive_kfold_splits(40, 5)[2]print("naive fold 2 overlaps:", cv.count_train_test_overlaps(t0, t1, naive_train, naive_test))
test 16 - 23 train [0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 33, 34, 35, 36, 37, 38, 39]purged [13, 14, 15, 24, 25, 26]10 CPCV splits; split 1 tests folds (0, 2)[[0 0 1 2 3] [1 4 4 5 6] [2 5 7 7 8] [3 6 8 9 9]]naive fold 2 overlaps: 6Walk-forward and the null, on the same example. evaluate rebuilds the price, the feature and
the labels from each null path, which is what lets the null see the bias above.
import numpy as npfrom openquant import cross_validation as cv
t0 = np.datetime64("2024-01-02T09:00") + np.arange(40) * np.timedelta64(1, "h")t1 = t0 + np.timedelta64(3, "h")train, test = cv.walk_forward_splits(t0, t1, n_splits=5, pct_embargo=0.15)[1]print("walk-forward fold 2: test", test.min(), "-", test.max(), "train", train.tolist())
# A null for a pipeline that fits the next 5-bar move on the price level.n, h = 300, 5t = np.arange(n)splits = cv.purged_kfold_splits(t, t + h, n_splits=5, pct_embargo=0.01)

def evaluate(returns, splits):    price = np.cumsum(returns)    x, y = price[t], price[t + h] > price[t]    hits = []    for tr, te in splits:        # Bet up when the price is below its training mean (what a fitted model learns).        hits.append(np.mean((x[te] < x[tr].mean()) == y[te]))    return float(np.mean(hits))

make_null = cv.bootstrap_returns(np.random.default_rng(0).standard_normal(n + h))null = cv.null_score_distribution(evaluate, splits, make_null, n_null=200, seed=1)wf = cv.walk_forward_splits(t, t + h, n_splits=5, pct_embargo=0.01)null_wf = cv.null_score_distribution(evaluate, wf, make_null, n_null=200, seed=1)print("k-fold null above chance:", null.mean() > 0.51, "| walk-forward null:", abs(null_wf.mean() - 0.5) < 0.01)
walk-forward fold 2: test 16 - 23 train [0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12]k-fold null above chance: True | walk-forward null: TrueThe list from purged_kfold_splits is a valid cv= for scikit-learn:
cross_val_score(model, X, y, cv=splits) or GridSearchCV(model, grid, cv=splits).
scikit-learn then passes sample_weight to fit but not to the scorer (the bug Snippet 7.4
fixes); hyperparameter-tuning’s
purged_search weights the score as well.
What to watch for
Section titled “What to watch for”- Sample weights are used to fit, not to score. Snippet 7.4 exists because scikit-learn’s
cross_val_scoredid exactly this; AFML’s version passes the test-fold weights to the metric. Heresample_weightreachesfitonly, so every test sample counts equally. If your weights matter — and with return attribution they differ by an order of magnitude — compute the weighted score yourself fromsplits. ml_cross_val_scorechecks shapes, not content. It returns an error ifyorsample_weightis not one entry per row ofx, if an index insplitsis beyondx, or ifpredict_probareturns the wrong number of values. An empty test set scoresNaNunder every rule, F1 included, so filter it out before averaging. BuildsplitswithPurgedKFoldand pass the samexandyit was sized for.samples_info_setsmust be in time order, one per row ofx. Folds are blocks of consecutive indices; the purge compares timestamps but the embargo counts positions. Unsorted input purges correctly and embargoes nonsense.- Purging can empty a training set. With long labels and many folds, the purged zone can
swallow a small dataset. Check
train.len()per fold; a fold trained on a handful of samples produces a score, not a meaningful one. ml_get_train_timesis the purge alone, on timestamps, for one or more test windows (Snippet 7.1). It applies no embargo and nothing else in the crate calls it; use it when you build your own splits, for instance several disjoint test blocks at once.- Features with memory need walk-forward, or a null through the same splits. Purged k-fold and CPCV fit middle folds on later samples, which flatters price levels and other slowly varying features even on random walks; see Features with memory.
- One path is not a backtest. Purged k-fold gives one out-of-sample prediction per
sample, hence one performance path.
cpcv_splitsandcpcv_pathsgive of them, andbacktesting-engine’srun_cpcvscores each. - CPCV grows fast. splits each hold their own index vectors: ,
is 252 splits. Only an overflowing count is an error (
TooManySplits).
Related modules
Section titled “Related modules”samplingandsample-weights— the in-sample half of the same overlap problem.backtesting-engine— walk-forward, purged CV and CPCV over these splits.fracdiff— fractionally differentiated features keep memory of the level, so score them walk-forward.hyperparameter-tuning— grid and randomised search underPurgedKFold.feature-importance— MDA scores features on purged folds.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.cross_validation.
cross_validation.purged_kfold_splits— Purged k-fold splits (AFML Snippet 7.3) as ``(train_idx, test_idx)`` numpy arrays.cross_validation.split_with_diagnostics— The folds of :func:`purged_kfold_splits`, each with why every excluded sample left.cross_validation.cpcv_splits— Combinatorial purged CV splits (AFML §12.4): one per choice of ``n_test_splits`` folds.cross_validation.cpcv_paths— The φ = k/N · C(N, k) CPCV backtest paths as an ``(n_paths, n_splits)`` int array.cross_validation.naive_kfold_splits— Unpurged contiguous k-fold: the leaky baseline AFML §7.3 warns against.cross_validation.count_train_test_overlaps— How many training samples have a label span intersecting some test sample's span.cross_validation.walk_forward_splits— Walk-forward splits over the folds of :func:`purged_kfold_splits`, forward-only.cross_validation.walk_forward_split_with_diagnostics— The splits of :func:`walk_forward_splits` as dicts, with the purged indices.cross_validation.null_score_distribution— Scores of a pipeline on ``n_null`` no-signal datasets, all run through the same splits.cross_validation.null_p_value— One-sided p-value of ``observed`` against a null distribution: P(null >= observed).cross_validation.bootstrap_returns— A no-signal generator for :func:`null_score_distribution`: returns drawn i.i.d.
Rustdoc for this commit, with every public item of openquant::cross_validation (after a crates.io release the same pages are on docs.rs):