
codependence
Correlation is the default way to say two series move together, and it has two shortcomings
that matter as soon as you cluster assets or screen features with it. It is not a distance:
it does not satisfy the triangle inequality, so “A is close to B and B is close to C” implies
nothing about A and C, and clustering algorithms that assume a metric can misbehave. And it
measures only linear dependence, so a feature that determines a target through a U-shape
scores zero. This module implements the remedies from López de Prado’s Machine Learning for
Asset Managers (2020), Chapter 3. It is the distance layer under hrp,
hcaa and onc.
Distances built on correlation
Section titled “Distances built on correlation”With the Pearson correlation of the two series:
| Function | Distance | Treats as |
|---|---|---|
angular_distance | as far apart as possible | |
absolute_angular_distance | identical | |
squared_angular_distance | identical |
All three are proper metrics on . Which one is right depends on the portfolio. For a long-only book, an asset with is the best diversifier available and belongs far away: use the first. For a long-short book the same asset is a perfect substitute with the sign flipped, and belongs in the same cluster: use the second or third. The squared version spreads out high correlations and compresses low ones.
Dependence without linearity
Section titled “Dependence without linearity”Distance correlation (Székely et al., 2007) compares the matrix of pairwise distances within to the one within , after double-centring each. It lies in and is zero only when the series are independent, which is not true of Pearson correlation.
Mutual information is the reduction in uncertainty about one variable from knowing the
other, , with the entropies estimated from histograms.
get_mutual_info(x, y, n_bins, normalize) with normalize = true divides by
, giving a number in .
Variation of information (Meilă, 2007) is the corresponding distance, : the uncertainty left in each variable once the other is known. It is a true metric. Normalised, it is divided by the joint entropy and lies in , with 0 meaning each variable determines the other.
Both estimates depend on the bin count. get_optimal_number_of_bins(n_obs, corr) implements
the Hacine-Gharbi et al. (2012) rules, which minimise the bias of the histogram estimator:
a univariate rule when corr is None, and for the joint histogram
Passing n_bins = None to the information functions applies this with the sample
correlation.
import mathimport random
from openquant import codependence as cd
rng = random.Random(6)n = 1000x = [rng.gauss(0, 1) for _ in range(n)]cases = {    "linear": [0.8 * v + 0.6 * rng.gauss(0, 1) for v in x],    "negative": [-0.8 * v + 0.6 * rng.gauss(0, 1) for v in x],    "parabola": [v * v + 0.3 * rng.gauss(0, 1) for v in x],    "independent": [rng.gauss(0, 1) for _ in x],}
def pearson(a, b):    ma, mb = sum(a) / len(a), sum(b) / len(b)    cov = sum((p - ma) * (q - mb) for p, q in zip(a, b))    return cov / math.sqrt(sum((p - ma) ** 2 for p in a) * sum((q - mb) ** 2 for q in b))
print("               corr   angular   abs.ang   dist.corr   norm.MI   norm.VI")for name, y in cases.items():    print(f"{name:12s} {pearson(x, y):+.3f}   {cd.angular_distance(x, y):7.3f}   "          f"{cd.absolute_angular_distance(x, y):7.3f}   {cd.distance_correlation(x, y):9.3f}   "          f"{cd.get_mutual_info(x, y, None, True):7.3f}   "          f"{cd.variation_of_information_score(x, y, None, True):7.3f}")
corr angular abs.ang dist.corr norm.MI norm.VIlinear +0.793 0.322 0.322 0.741 0.261 0.851negative -0.787 0.945 0.327 0.734 0.240 0.864parabola +0.095 0.673 0.673 0.521 0.584 0.722independent -0.022 0.715 0.699 0.049 0.010 0.995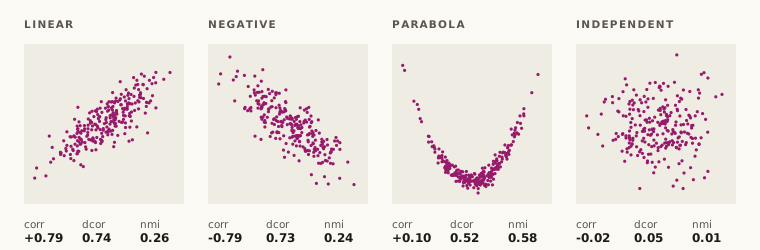
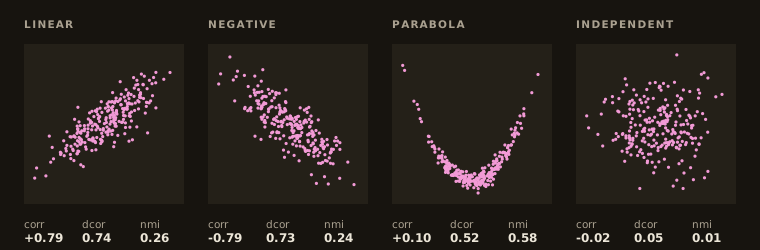
The parabola row is the reason the module exists. Correlation puts at 0.095,
indistinguishable from the independent series on the row below, and the angular distances
follow it. Distance correlation puts it at 0.52 and mutual information ranks it as the
strongest relationship of the four, which it is: it is the least noisy. The negative row
shows the other choice: plain angular distance places the mirror-image series at 0.945, as
far away as anything can be, and the absolute version places it beside the linear one.
From Rust
Section titled “From Rust”use openquant::codependence::{ absolute_angular_distance, angular_distance, distance_correlation, get_optimal_number_of_bins, variation_of_information_score, CodependenceError,};
let x: Vec<f64> = (0..=200).map(|i| f64::from(i) / 100.0 - 1.0).collect();let mirrored: Vec<f64> = x.iter().map(|v| -v).collect();let squared: Vec<f64> = x.iter().map(|v| v * v).collect();
// rho = -1: maximal angular distance, zero absolute angular distance.assert!((angular_distance(&x, &mirrored)? - 1.0).abs() < 1e-12);assert!(absolute_angular_distance(&x, &mirrored)?.abs() < 1e-7);
// y = x^2 on a symmetric range is uncorrelated with x, and clearly dependent on it.assert!((angular_distance(&x, &squared)? - 0.5f64.sqrt()).abs() < 1e-3);assert!(distance_correlation(&x, &squared)? > 0.4);
// A one-to-one relationship leaves no uncertainty either way.assert!(variation_of_information_score(&x, &mirrored, None, true)?.abs() < 1e-12);
assert_eq!(get_optimal_number_of_bins(1_000, None)?, 15);assert_eq!(get_optimal_number_of_bins(1_000, Some(0.9))?, 13);assert!(matches!(angular_distance(&x, &[1.0]), Err(CodependenceError::InputLengthMismatch)));What to watch for
Section titled “What to watch for”- Distance correlation is quadratic in memory. It builds two matrices of
f64: 16 MB at a thousand observations, 1.6 GB at ten thousand, and an allocation failure not far beyond. Subsample, or use mutual information, which is linear. - Mutual information from histograms is biased upward on small samples, and the size of
the bias depends on the bin count. Compare values only across series of the same length
and binning. The
independentrow above is 0.010, not 0; with 100 observations it would be several times that. - Bins are equal-width between the minimum and maximum. One outlier stretches the range and pushes nearly every observation into one or two bins, which collapses the entropy estimate. Winsorise, or rank-transform the series first; ranks make every marginal uniform and the estimate depends only on the dependence.
- Normalised mutual information is not a distance, and is not one either. For clustering use variation of information.
- These are pairwise functions. There is no matrix helper here; build the distance matrix
yourself, or use
hrpandhcaa, which do so internally from correlation. - Serial dependence is ignored. Every measure treats the observations as exchangeable pairs. Two trending price levels will look dependent under all of them; pass returns, or fractionally differenced series.
Related modules
Section titled “Related modules”hrp,hcaa— hierarchical allocation on a correlation distance.onc— optimal number of clusters, for features or for backtest trials.feature-importance— cluster substitutable features before measuring importance.fingerprint— non-linear effects inside a fitted model.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.codependence.
codependence.angular_distance— Angular distance `sqrt((1 - rho) / 2)` from the Pearson correlation `rho` of two series.codependence.absolute_angular_distance— Absolute angular distance `sqrt((1 - |rho|) / 2)` from the Pearson correlation of two series.codependence.squared_angular_distance— Squared angular distance `sqrt((1 - rho^2) / 2)` from the Pearson correlation of two series.codependence.distance_correlation— Distance correlation of two series (Székely et al., 2007).codependence.get_mutual_info— Mutual information `I[X;Y] = H[X] + H[Y] - H[X,Y]` from an equal-width 2-D histogram.codependence.variation_of_information_score— Variation of information `VI[X;Y] = H[X] + H[Y] - 2 I[X;Y]` of two series (Meilă, 2007).codependence.get_optimal_number_of_bins— Histogram bin count that minimises the bias of entropy estimates.
Rustdoc for this commit, with every public item of openquant::codependence (after a crates.io release the same pages are on docs.rs):