
onc
Most clustering algorithms need to be told how many clusters to find, and the answer is usually the thing you wanted to learn. How many distinct bets are in this portfolio? How many genuinely different strategies are in these two hundred backtests? The Optimal Number of Clusters algorithm (López de Prado and Lewis, 2019; Machine Learning for Asset Managers, Chapter 4) answers by trying every count and keeping the partition whose clusters are most clearly separated. It is not from AFML. Its two uses in this library’s workflow are grouping substitutable features before measuring importance and counting the effective number of trials for a deflated Sharpe ratio.
The algorithm
Section titled “The algorithm”Observations. Convert the correlation matrix to the distance . Each item is then represented by its row of that matrix, its distances to every other item, so two items are close when they relate to everything else in the same way. That is more robust than comparing the pair alone.
Quality. For an item , let be its mean distance to the other members of its cluster and its mean distance to the members of the nearest other cluster. Its silhouette (Rousseeuw, 1987) is
which is near 1 for an item deep inside a well-separated cluster and negative for one that sits closer to a neighbouring cluster. The quality of a whole partition is the -statistic of the silhouettes, : high when silhouettes are large and uniformly so.
Base clustering. Run k-means for every from 2 to , repeat times each with
different initialisations, and keep the partition with the highest . Each run is one
k-means++ initialisation followed by Lloyd’s algorithm, as the book’s Snippet 4.1 does with
scikit-learn’s KMeans(n_init=1). Equal goes to the higher mean silhouette.
Higher-level clustering. Compute per cluster. Clusters below the average are pooled and the whole procedure is run again on just their members, on the view that a poor cluster may be several real ones merged. The re-clustered partition is kept if it scores better.
get_onc_clusters(corr, repeat) returns an OncResult: clusters, a map from cluster label
to member indices; silhouette_scores, one per item in the original order; and
ordered_correlation, the matrix permuted so that clusters are contiguous.
get_onc_clusters_with_seed(corr, repeat, seed) is the same with the seed of the random stream
given; from Python it is the seed argument, 42 by default.
Recovering planted clusters
Section titled “Recovering planted clusters”import random
from openquant import onc
# Twelve series in three planted groups of sizes 5, 4 and 3, shuffled so that the correlation# matrix shows no structure as given.rng = random.Random(7)group_of = [0] * 5 + [1] * 4 + [2] * 3rng.shuffle(group_of)series = []factors = [[rng.gauss(0, 1) for _ in range(600)] for _ in range(3)]for g in group_of: series.append([0.8 * f + 0.6 * rng.gauss(0, 1) for f in factors[g]])
def corr(a, b): n = len(a) ma, mb = sum(a) / n, sum(b) / n cov = sum((x - ma) * (y - mb) for x, y in zip(a, b)) return cov / (sum((x - ma) ** 2 for x in a) * sum((y - mb) ** 2 for y in b)) ** 0.5
matrix = [[corr(a, b) for b in series] for a in series]result = onc.get_onc_clusters(matrix, 5)
print("planted groups:", group_of)for label, members in sorted(result["clusters"].items()): print(f"cluster {label}: members {members} planted group {sorted({group_of[i] for i in members})}")silhouettes = result["silhouette_scores"]print(f"mean silhouette {sum(silhouettes) / len(silhouettes):.2f}")planted groups: [1, 2, 0, 2, 1, 0, 2, 0, 0, 1, 0, 1]cluster 0: members [2, 5, 7, 8, 10] planted group [0]cluster 1: members [0, 4, 9, 11] planted group [1]cluster 2: members [1, 3, 6] planted group [2]mean silhouette 0.48Nothing told the algorithm to look for three clusters, or that their sizes differ. It returned three, and each holds exactly the members of one planted group.
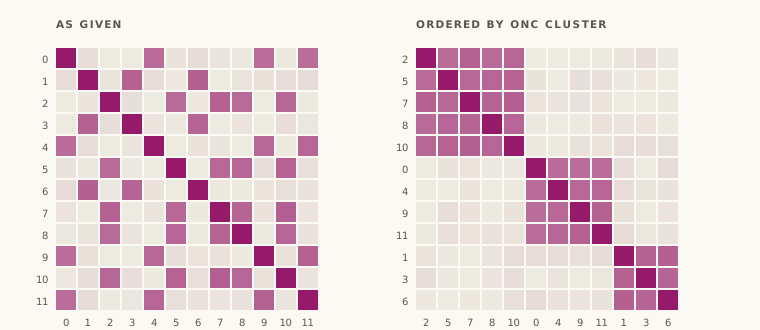
ordered_correlation.From Rust
Section titled “From Rust”use nalgebra::DMatrix;use openquant::onc::{get_onc_clusters, OncError};
// Two blocks of three: 0.8 within a block, 0.1 across.let block = |i: usize| i / 3;let corr = DMatrix::from_fn(6, 6, |i, j| { if i == j { 1.0 } else if block(i) == block(j) { 0.8 } else { 0.1 }});
let result = get_onc_clusters(&corr, 3)?;assert_eq!(result.clusters.len(), 2);let mut found: Vec<Vec<usize>> = result.clusters.values().cloned().collect();found.sort();assert_eq!(found, vec![vec![0, 1, 2], vec![3, 4, 5]]);
// One silhouette per item, all clearly positive for a clean partition.assert_eq!(result.silhouette_scores.len(), 6);assert!(result.silhouette_scores.iter().all(|s| *s > 0.5));
assert_eq!(get_onc_clusters(&corr, 0).unwrap_err(), OncError::InvalidRepeat);What to watch for
Section titled “What to watch for”- The higher-level step runs only on messy inputs. Re-clustering happens when more than two clusters score below the average -statistic, which clean inputs like the example never reach. The re-clustered partition is kept only if its mean cluster -statistic beats that of the clusters it replaced, as in Snippet 4.2. Until #107 was fixed the comparison was inverted, so on matrices that reached this step ONC returned the worse of its two partitions.
- ONC is a random search, and on real data its answer can depend on the seed. The
partition kept is the best of
repeatk-means runs per , and the best one may be a k-means local optimum that few initialisations reach. The same matrix,repeatand seed always give the same answer, and clean structure like the example above comes back the same under any seed. Real data need not: on the 30 features of the breast-cancer data set, withrepeat=50, different seeds return eight, seven, six or five clusters, every one of them a merger of the same eight groups; scikit-learn’s ONC does the same. Run a few seeds, and raiserepeat, before reading much into one partition. Until #218 the initialisations were random points instead of k-means++, and on that data most seeds returned a two-cluster partition that split those groups. - Cost grows as the cube of the number of items or worse. Every up to is tried,
repeattimes, and each silhouette pass is quadratic. A few hundred items is comfortable; thousands is not, and the recursion multiplies it. - It returns at least two clusters, except on identical rows. The search starts at , so a matrix with no structure still comes back partitioned. A low mean silhouette, or a silhouette -statistic near zero, is the sign that the clusters are not real. The one exception is a matrix whose rows are all the same, such as all ones: there is nothing to separate, and the result is a single cluster of every item with silhouettes of 0.
- Negative correlation is distance, not similarity. With a pair at is as far apart as possible. If a strategy and its mirror image should count as the same bet, take absolute correlations first.
- The input must be a correlation matrix: square, with at least two rows. Values are
clamped to but symmetry and a unit diagonal are not checked. From Python it is a
list of lists, and
clusterscomes back as a dict keyed by label.
Related modules
Section titled “Related modules”codependence— the distance used here, and alternatives that see non-linear dependence.hrp,hcaa— allocation over a hierarchical tree rather than a flat partition.feature-importance— cluster features, then measure importance per cluster.backtest-statistics— the number of clusters of trial returns is the to deflate by.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.onc.
onc.get_onc_clusters— Optimal Number of Clusters (ONC) partition of a correlation matrix.
Rustdoc for this commit, with every public item of openquant::onc (after a crates.io release the same pages are on docs.rs):