
feature_diagnostics
This is the notebook-facing side of AFML Chapter 8: hand it a feature matrix and labels and
it returns importance tables ready to read or plot. It is written in pure Python and is
independent of the Rust feature_importance module — it
does not call it, and it brings its own model. Read that page for what MDI, MDA and SFI mean
and how each can mislead; this page covers what the Python functions do with them.
The model is fixed
Section titled “The model is fixed”Every function here fits the same model: a logistic regression of the 0/1 label on the
features, fitted by Newton’s method (iteratively reweighted least squares) with a tiny L2
penalty of 0.001 that keeps the coefficients finite when a fold is perfectly separable.
sample_weight weights each row’s log-likelihood. It has no dependencies, and it is the
first thing to know about any number this module reports.
Importance is always importance to a model. A feature that matters through a threshold, an interaction, or any non-monotone effect is invisible to a linear model and will be scored as noise here.
Use these reports for screening. Measure importance for the model you will trade with
feature_importance or your own code.
Purged folds are mandatory
Section titled “Purged folds are mandatory”mda_importance, sfi_importance and substitution_effect_report cross-validate on purged
k-fold splits and need event_end_indices: for each row, the row index at which its label
is resolved. Omit it and they raise, with an explanation, rather than quietly running
unpurged. allow_unpurged=True is the explicit opt-out, and the returned cv block then
records "purged": False. This Python splitter embargoes both sides of each test fold, counted from the fold’s edges.
That is stricter than the Rust PurgedKFold, which embargoes only after the fold, starting
where the purge ends (Snippet 7.3).
Three rankings of the same features
Section titled “Three rankings of the same features”The data follow AFML’s synthetic experiment (§8.6) in miniature: two informative features, a noisy copy of the first, and two of pure noise.
import random
from openquant import feature_diagnostics as fd
# 1,200 samples. Each label resolves five rows after it starts, so neighbours overlap.rng = random.Random(8)n = 1200a = [rng.gauss(0, 1) for _ in range(n)]b = [rng.gauss(0, 1) for _ in range(n)]names = ["a", "a_copy", "b", "noise_1", "noise_2"]X = [[a[i], a[i] + rng.gauss(0, 0.2), b[i], rng.gauss(0, 1), rng.gauss(0, 1)] for i in range(n)]y = [1.0 if a[i] + 0.6 * b[i] + rng.gauss(0, 0.7) > 0 else 0.0 for i in range(n)]ends = [min(i + 5, n - 1) for i in range(n)]
common = dict(feature_names=names, event_end_indices=ends, n_splits=5, pct_embargo=0.01)mdi = {r["feature"]: r["mean"] for r in fd.mdi_importance(X, y, feature_names=names)["records"]}mda = {r["feature"]: r["mean"] for r in fd.mda_importance(X, y, **common)["records"]}sfi = {r["feature"]: r["mean"] for r in fd.sfi_importance(X, y, **common)["records"]}
print("feature      MDI     MDA     SFI")for f in names:    print(f"{f:8s}  {mdi[f]:6.3f}  {mda[f] + 0.0:6.3f}  {sfi[f]:6.3f}")
pair = fd.substitution_effect_report(X, y, **common)["pair_records"][0]print(f"{pair['feature_a']} ~ {pair['feature_b']}: corr {pair['corr']:.3f}, "      f"singly {pair['single_sum']:.3f}, jointly {pair['group_importance']:.3f}")
feature MDI MDA SFIa 0.538 0.625 -0.474a_copy 0.093 0.014 -0.482b 0.337 0.410 -0.633noise_1 0.018 -0.001 -0.696noise_2 0.015 -0.005 -0.695a ~ a_copy: corr 0.981, singly 0.639, jointly 0.656Read across the a_copy row. MDA says it is nearly worthless, 0.014 against 0.625 for a.
SFI says it is nearly as good as a: −0.482 against −0.474. Both are right. Given a, the model
has no use for a noisier copy of it, and damaging the copy costs nothing; on its own, the
copy carries almost all of a’s information. This is the substitution effect, and it is the
reason to never drop a feature on one method’s say-so: remove a from this set and a_copy
becomes the most important feature in it.
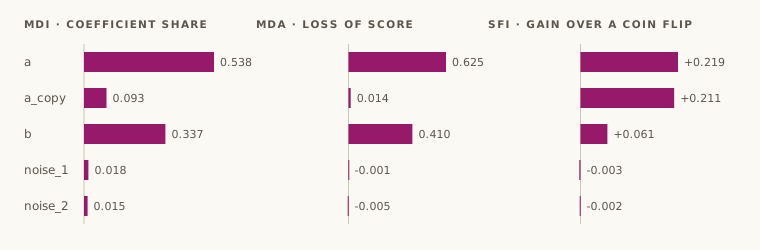
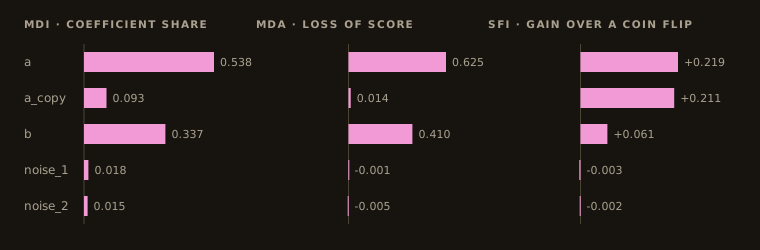
SFI levels are out-of-sample log losses, so compare them with a coin flip’s −0.693. The
informative features beat it, b by less because it carries less of the signal on its own;
the noise features land just below it, which is what fitting pure noise costs out of sample.
What each function returns
Section titled “What each function returns”All return a dict. The importance functions share a shape: table (a Polars frame with
feature, mean, std, stderr, sorted by mean), records (the same as a list of
dicts), viz_payload (for viz), and for the cross-validated ones a cv
block recording the split settings and mean_base_score.
| Function | Notes |
|---|---|
mda_importance | scoring is "neg_log_loss" (default), "accuracy" or "f1" (threshold 0.5); test-fold scores use sample_weight |
sfi_importance | raw cross-validated score per feature; compare with −0.693 for log loss |
mdi_importance | not MDI — see below |
orthogonalize_features_pca | standardise, then project on the components explaining variance_threshold (default 0.95) |
substitution_effect_report | for each pair with abs(corr) ≥ corr_threshold (default 0.9): the sum of their single MDAs, the MDA of damaging both at once, and their ratio; plus MDA on PCA-orthogonalised features |
feature_screen_report | no model: coverage, variance and pairwise correlation checks, with selected_features and rejection_reasons |
In the substitution report, dilution_ratio is joint importance over the sum of single
importances, and flag_substitution_risk is set when it exceeds 1.15. In the example
it is 1.03 and unflagged: the linear model concentrated on a and never split credit with
the copy. A tree ensemble on the same data would split it, and the ratio would be well above
one. The report is only as sensitive as the fixed model lets it be.
What to watch for
Section titled “What to watch for”mdi_importanceis not mean decrease impurity. There are no trees. It bootstraps the rowsn_estimatorstimes, fits the linear model to each, and averages the normalised absolute coefficients. That is a reasonable in-sample ranking if the features are on a common scale — it does not standardise them, so a feature measured in basis points will outrank the same feature measured in percent. Standardise first, or ignore this column.- MDA of a very persistent feature is still somewhat understated. The column is shuffled
within each test fold, as in Snippet 8.3, with
random.Random(seed)(seed=42by default, also taken bysubstitution_effect_report, and echoed incv["seed"]). When a feature moves so slowly that one fold spans only a few of its swings, shuffling among the fold’s bunched-together values damages it less than shuffling the whole sample would. Up to an autocorrelation of about 0.95 this is negligible; at 0.99 it is noticeable. Before #98 was fixed the column was rotated by a few rows instead, and such a feature scored 0.103 instead of 0.646. feature_screen_reportkeeps the higher-variance feature of a correlated pair. On the example it rejectsaand keepsa_copy, the noisier one, because noise adds variance. The screen never looks aty, so it cannot know better. Use it to find the pairs; choose which member to keep yourself.- It is pure Python and quadratic in places. Fine for a few thousand rows and a few dozen features in a notebook. For more, use the Rust module.
event_end_indicesare row positions, not timestamps, and must be at or after each row’s own index. Values past the last row are clipped.
Related modules
Section titled “Related modules”feature-importance— the methods themselves, for any model, in Rust.cross-validation— purging and embargo.labeling— whereevent_end_indicescome from.viz— renders theviz_payloadeach report carries.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.feature_diagnostics.
feature_diagnostics.mda_importance— Estimate out-of-sample permutation feature importance (MDA, AFML section 8.3.2).feature_diagnostics.sfi_importance— Score each feature on its own out of sample (single feature importance, AFML 8.4.1).feature_diagnostics.mdi_importance— Estimate feature importance from bootstrapped logistic-regression coefficients.feature_diagnostics.orthogonalize_features_pca— Project standardized features onto their leading principal components (AFML 8.4.2).feature_diagnostics.substitution_effect_report— Flag correlated feature pairs whose MDA importance is diluted by substitution.feature_diagnostics.feature_screen_report— Run lightweight feature QA checks for notebook discovery loops.