
ensemble_methods
This module does not train ensembles. It answers the question that comes before training
one: will averaging help here? AFML’s answer in Chapter 6 is a single formula, and most of
the module is that formula and the quantities that go into it. The Python module is named
openquant.ensemble; the Rust module is ensemble_methods.
Why bagging works, and when it does not
Section titled “Why bagging works, and when it does not”Average estimators whose predictions each have variance and whose pairwise correlation averages . The variance of the average is (§6.3.1)
The second term is what more estimators buy, and it goes to zero. The first term is a floor that no number of estimators moves. With independent estimators variance falls as ; at , a thousand estimators remove at most a tenth of it.
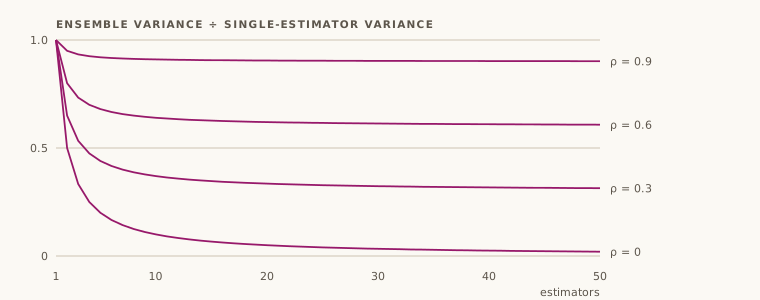
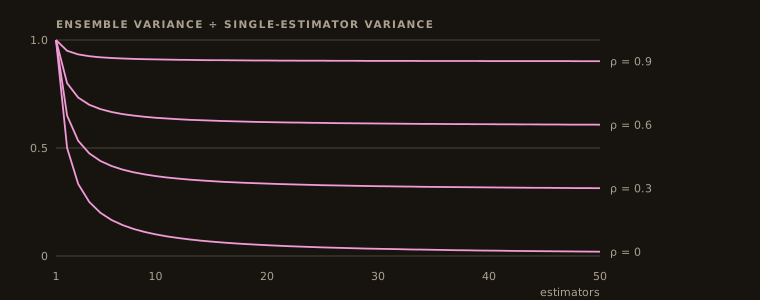
This is why overlapping labels matter so much to bagging in finance (§6.3.3). Bootstrap
samples drawn from redundant observations are nearly the same sample, so the estimators
fitted to them are nearly the same estimator, and is high before any modelling
choice has been made. The levers are the ones in Chapter 4: fewer overlapping labels,
sequential bootstrapping, a max_samples
set to the average uniqueness, and feature
subsampling.
The example builds 25 models whose errors share a common component, measures from their predictions, and checks the formula against the variance actually realised by the average.
import randomfrom statistics import pvariance
from openquant import ensemble
# 25 models forecast 4,000 targets. Each model's error is a shared component plus its own,# mixed so that any two models' errors correlate at about rho. Each has error variance 1.rng = random.Random(11)n_models, n_obs = 25, 4000truth = [rng.gauss(0, 1) for _ in range(n_obs)]
print(" rho   measured corr   formula   realised")for rho in (0.0, 0.3, 0.9):    shared = [rng.gauss(0, 1) for _ in range(n_obs)]    errors = [[rho**0.5 * s + (1 - rho) ** 0.5 * rng.gauss(0, 1) for s in shared]              for _ in range(n_models)]    corr = ensemble.average_pairwise_prediction_correlation(errors)    formula = ensemble.bagging_ensemble_variance(1.0, corr, n_models)    predictions = [[t + e for t, e in zip(truth, row)] for row in errors]    bagged = ensemble.aggregate_regression_mean(predictions)    realised = pvariance([b - t for b, t in zip(bagged, truth)])    print(f"{rho:4.1f}   {round(corr, 3) + 0.0:13.3f}   {formula:7.3f}   {realised:8.3f}")
decision = ensemble.recommend_bagging_vs_boosting(0.62, 0.9, 0.4, 1.0, n_models)print(decision["recommended"], f"{decision['expected_variance_reduction']:.3f}")
rho measured corr formula realised 0.0 0.000 0.040 0.040 0.3 0.292 0.321 0.317 0.9 0.902 0.906 0.920boosting 0.096Twenty-five independent models cut error variance to 4% of a single model’s. Twenty-five
models correlated at 0.9 cut it to 92%. Note what the correlation was measured on: the models’
errors. average_pairwise_prediction_correlation takes whatever rows it is given, and on
raw predictions of a common target it mostly measures that they all track the target. Pass
residuals, or predictions on a de-meaned target, to get the the formula means.
The other functions
Section titled “The other functions”| Function | What it returns |
|---|---|
aggregate_regression_mean(rows) | element-wise mean of the models’ predictions |
aggregate_classification_vote(rows) | majority vote over 0/1 labels; a tie goes to 1 |
aggregate_classification_probability_mean(rows, threshold) | mean probability per observation, and the label at threshold |
bootstrap_sample_indices(n, size, seed) | size uniform draws from 0..n, reproducible |
bias_variance_noise(y_true, rows, y_expected=None) | squared bias, variance, noise and MSE across models, averaged over observations; noise only when the noiseless target y_expected is given |
recommend_bagging_vs_boosting(...) | the formula above plus a rule-of-thumb label |
recommend_bagging_vs_boosting returns Boosting if base accuracy is below 0.55, or
, or label redundancy is at least 0.70, and Bagging otherwise. The
reasoning follows §6.6 — bagging addresses variance and overfitting, boosting addresses bias,
and bagging cannot rescue a learner that is barely better than chance (§6.3.2). The three
cut-offs are this library’s, not the book’s. AFML’s own conclusion is that bagging is
generally preferable in finance because overfitting is the greater danger; treat the label as
a prompt to look at the inputs. The numbers that carry information are
expected_bagging_variance and expected_variance_reduction.
From Rust
Section titled “From Rust”use openquant::ensemble_methods::{ aggregate_classification_vote, bagging_ensemble_variance, recommend_bagging_vs_boosting, EnsembleError, EnsembleMethod,};
// The floor: at rho = 0.9, a thousand estimators remove under a tenth of the variance.let v = bagging_ensemble_variance(1.0, 0.9, 1_000)?;assert!((v - 0.9001).abs() < 1e-12);// Independent estimators: 1/N.assert!((bagging_ensemble_variance(2.0, 0.0, 50)? - 0.04).abs() < 1e-12);
// Two of three vote 1; a 1-1 tie also resolves to 1.assert_eq!(aggregate_classification_vote(&[vec![1, 0], vec![1, 0], vec![0, 0]])?, vec![1, 0]);assert_eq!(aggregate_classification_vote(&[vec![1], vec![0]])?, vec![1]);assert_eq!(aggregate_classification_vote(&[vec![2]]), Err(EnsembleError::NonBinaryLabels));
let decision = recommend_bagging_vs_boosting(0.62, 0.30, 0.40, 1.0, 25)?;assert_eq!(decision.recommended, EnsembleMethod::Bagging);assert!((decision.expected_bagging_variance - 0.328).abs() < 1e-12);What to watch for
Section titled “What to watch for”sequential_bootstrap_sample_indicesissampling.seq_bootstrapwith a seed. The sameseedgives the same indices, but not the indicesbootstrap_sample_indicesgives for that seed: the two draw from different distributions.noiseinbias_variance_noiseneeds the noiseless target. Against the observedy_truealone, bias² + variance = MSE exactly and noise cannot be told apart from bias, sonoiseisNoneandbias_sqmeans “bias plus noise”. Passy_expected= E[y|x] (known in a simulation, as in §6.2) and bias² is measured against it,noise= mean((y_true − y_expected)²), and bias² + variance + noise = MSE in expectation (not exactly in one sample).- The formula assumes equal variances and one average correlation. A few strong models among many weak ones, or clusters of near-identical models, break it; the realised column in the example is the honest check.
- From Python, vote and label outputs are lists of 0/1 ints.
bias_variance_noisereturns a plain tuple(bias_sq, variance, noise, mse)withnoiseNoneunlessy_expectedis passed, andrecommend_bagging_vs_boostinga dict. - Majority vote discards confidence. Averaging probabilities keeps it, and the averaged
probability is what
bet-sizingwants as input.
Related modules
Section titled “Related modules”sampling— uniqueness and the sequential bootstrap, which attack at the source.sb-bagging— a bagging ensemble over overlapping labels.cross-validation— score the ensemble without leakage.feature-importance— what the ensemble learned from.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.ensemble.
ensemble.bagging_ensemble_variance— Variance of the average of N estimators, `sigma2 * (rho + (1 - rho) / N)` (AFML 6.3.1).ensemble.average_pairwise_prediction_correlation— Mean Pearson correlation over all pairs of model rows: the rho-bar of AFML section 6.3.1.ensemble.bias_variance_noise— Bias-variance-noise decomposition of an ensemble's forecasts (AFML section 6.2).ensemble.aggregate_regression_mean— Element-wise mean of the models' predictions: the bagged regression forecast (AFML 6.3).ensemble.aggregate_classification_vote— Majority vote over binary class predictions (AFML section 6.3.2).ensemble.aggregate_classification_probability_mean— Mean predicted probability per observation, and the label it implies at `threshold`.ensemble.bootstrap_sample_indices— Draw a uniform bootstrap sample of indices, with replacement (AFML section 6.3).ensemble.sequential_bootstrap_sample_indices— Draw label indices with the sequential bootstrap (AFML section 4.5.1, Snippets 4.5-4.6).ensemble.recommend_bagging_vs_boosting— Expected bagging variance plus a rule-of-thumb bagging-or-boosting label (AFML 6.6).
Rustdoc for this commit, with every public item of openquant::ensemble_methods (after a crates.io release the same pages are on docs.rs):