
hyperparameter_tuning
Tuning is where cross-validation leakage does the most damage, because the search optimises against it. If overlapping labels inflate every fold’s score a little, the configuration that wins is the one best at exploiting the overlap — usually the most flexible one. AFML’s Chapter 9 therefore changes two things about an ordinary grid search: the folds are purged and embargoed, and the score is one that punishes confident mistakes. This module is that search.
How a search is set up
Section titled “How a search is set up”You supply a builder, a closure from a ParamSet to a fresh model implementing
SimpleClassifier. A ParamSet is a map from name to
HyperParamValue (Int, Float or Bool), read back with as_i64, as_f64 and
as_bool. The data go in a SearchData: features, 0/1 labels, optional sample weights, and
the (start, end) span of every label, which is what the purge needs.
grid_search(builder, grid, data, n_splits, pct_embargo, scoring)tries every combination of the listed values.randomized_search(builder, space, n_iter, seed, data, n_splits, pct_embargo, scoring)drawsn_iterparameter sets from distributions:Choice,Uniform,LogUniform, orIntRangeInclusive. It is reproducible for a givenseed.
Both return a SearchResult: best_params, best_score, and every SearchTrial with its
per-fold scores. Each trial builds a new model per fold, fits it with the training weights,
and scores the test fold with the test weights — the correction Snippet 9.1 makes to
scikit-learn.
Scoring decides what you find
Section titled “Scoring decides what you find”SearchScoring | |
|---|---|
NegLogLoss | weighted mean log-likelihood of the true label; probabilities clipped at |
Accuracy | weighted share of labels matched at a 0.5 threshold |
BalancedAccuracy | mean of per-class recall, over the classes present in the fold |
AFML’s argument for log loss (§9.4) is about position sizing. Accuracy counts a wrong call
made with 51% confidence the same as one made with 99%, but a strategy that
sizes by probability loses far more on the second. The example makes
the point with a model whose only hyperparameter is how confident it is: k scales the
score inside the sigmoid and changes no prediction’s side of 0.5.
use std::collections::BTreeMap;
use chrono::{Duration, NaiveDate};use openquant::cross_validation::SimpleClassifier;use openquant::hyperparameter_tuning::{    grid_search, randomized_search, HyperParamValue, ParamSet, RandomParamDistribution,    SearchData, SearchScoring,};
/// Scores by the difference of class means, squashed by a sigmoid of sharpness `k`.struct MeanDiff { k: f64, w: Vec<f64>, b: f64 }
impl SimpleClassifier for MeanDiff {    fn fit(&mut self, x: &[Vec<f64>], y: &[f64], _sample_weight: Option<&[f64]>) {        let m = x[0].len();        let (mut pos, mut neg, mut n_pos, mut n_neg) = (vec![0.0; m], vec![0.0; m], 0.0, 0.0);        for (row, label) in x.iter().zip(y) {            let (sum, count) =                if *label > 0.5 { (&mut pos, &mut n_pos) } else { (&mut neg, &mut n_neg) };            *count += 1.0;            row.iter().enumerate().for_each(|(j, v)| sum[j] += v);        }        self.w = (0..m).map(|j| pos[j] / n_pos - neg[j] / n_neg).collect();        self.b = -(0..m).map(|j| self.w[j] * (pos[j] / n_pos + neg[j] / n_neg) / 2.0).sum::<f64>();    }    fn predict_proba(&self, x: &[Vec<f64>]) -> Vec<f64> {        let z = |r: &Vec<f64>| r.iter().zip(&self.w).map(|(a, b)| a * b).sum::<f64>() + self.b;        x.iter().map(|r| 1.0 / (1.0 + (-self.k * z(r)).exp())).collect()    }}
// Reproducible noise in [-1, 1) from a hash, so the example needs no RNG.fn noise(i: usize, salt: u64) -> f64 {    let mut h = (i as u64).wrapping_mul(0x9E37_79B9_7F4A_7C15) ^ salt.wrapping_mul(0xD1B5_4A32_D192_ED03);    h ^= h >> 31;    h = h.wrapping_mul(0x7FB5_D329_728E_A185);    h ^= h >> 27;    (h >> 11) as f64 / (1u64 << 53) as f64 * 2.0 - 1.0}
let n = 600;let x: Vec<Vec<f64>> = (0..n).map(|i| vec![noise(i, 1), noise(i, 2), noise(i, 3)]).collect();let y: Vec<f64> = (0..n)    .map(|i| f64::from(u8::from(x[i][0] + 0.5 * x[i][1] + 0.4 * noise(i, 9) > 0.0)))    .collect();let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let info: Vec<_> =    (0..n as i64).map(|i| (open + Duration::hours(i), open + Duration::hours(i + 3))).collect();
let data = || SearchData { x: &x, y: &y, sample_weight: None, samples_info_sets: &info };let build = |p: &ParamSet| MeanDiff { k: p["k"].as_f64().unwrap(), w: vec![], b: 0.0 };let grid = BTreeMap::from([(    "k".to_string(),    [0.5, 2.0, 4.0, 8.0, 32.0].map(HyperParamValue::Float).to_vec(),)]);
let by_loss = grid_search(build, &grid, data(), 5, 0.01, SearchScoring::NegLogLoss)?;assert_eq!(by_loss.best_params["k"], HyperParamValue::Float(8.0));assert!((by_loss.best_score + 0.2243).abs() < 1e-4);
// Accuracy cannot tell the five apart, and a tie goes to the last one tried.let by_accuracy = grid_search(build, &grid, data(), 5, 0.01, SearchScoring::Accuracy)?;assert!(by_accuracy.trials.iter().all(|t| (t.mean_score - 0.8950).abs() < 1e-4));assert_eq!(by_accuracy.best_params["k"], HyperParamValue::Float(32.0));
// A log-uniform draw covers three orders of magnitude evenly and lands near the same optimum.let space =    BTreeMap::from([("k".to_string(), RandomParamDistribution::LogUniform { low: 0.1, high: 100.0 })]);let random = randomized_search(build, &space, 12, 7, data(), 5, 0.01, SearchScoring::NegLogLoss)?;assert!((random.best_params["k"].as_f64().unwrap() - 8.253).abs() < 1e-3);
Mean score by k, from the two grid searches:
k neg log loss accuracy 0.5 -0.5941 0.8950 2.0 -0.3933 0.8950 4.0 -0.2745 0.8950 8.0 -0.2243 0.8950 32.0 -0.4711 0.8950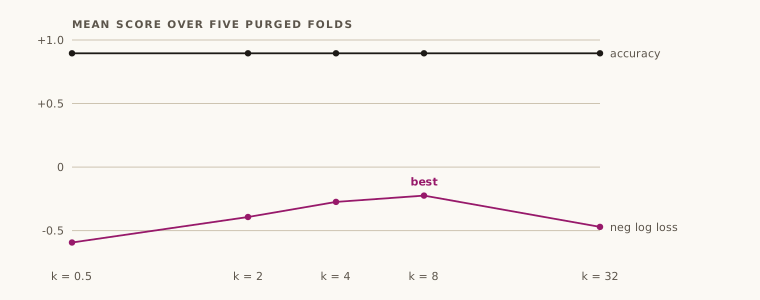
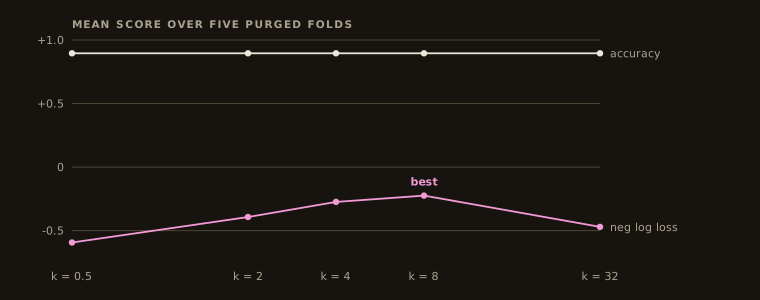
Accuracy returned k = 32, the second-worst setting by log loss, and it did so by accident
of ordering. A model tuned that way states near-certainty on calls it gets right 90% of
the time, and a probability-sized book built on it is badly over-levered.
Why log-uniform
Section titled “Why log-uniform”Many hyperparameters — regularisation strength, learning rate, an SVM’s C and gamma —
matter by order of magnitude: the difference between 0.01 and 0.1 is as large as between 10
and 100. A uniform draw over puts 90% of its samples above 10 and almost none
where the lower decades are. LogUniform draws uniformly (§9.3.1), so every decade
gets equal attention; sample_log_uniform(low, high, rng) is the same draw on its own. Both
bounds must be positive.
Random search is also usually the better use of a fixed budget when only some parameters matter, because a grid spends most of its trials varying the ones that do not (Bergstra and Bengio, 2012).
From Python
Section titled “From Python”grid_search and randomized_search build and fit a Rust SimpleClassifier, so they are not
bound. The parts that need no model are, and the fit loop runs in Python:
expand_param_grid(grid)andsample_param_sets(space, n_iter, seed)return the candidates the Rust searches evaluate, in the same order.spacevalues are("choice", [values]),("uniform", low, high),("log_uniform", low, high)or("int", low, high).classification_score(y_true, probabilities, sample_weight=None, scoring="neg_log_loss")is the weighted score above;scoringmay also be"accuracy"or"balanced_accuracy".purged_search(make_estimator, param_sets, X, y, t0, t1, *, n_splits, pct_embargo, scoring, sample_weight)builds a model per candidate withmake_estimator(params), fits it on each purged fold with the training weights, and scores the test fold withclassification_scoreand the test weights, asgrid_searchdoes. It returnsbest_params,best_scoreandtrials.
import numpy as npfrom openquant import hyperparameter_tuning as ht

class Threshold:    """P(y = 1) is a logistic in the one feature, centred on `threshold`."""
    def __init__(self, params):        self.threshold, self.sharpness = params["threshold"], params["sharpness"]
    def fit(self, X, y, sample_weight=None):        return self
    def predict_proba(self, X):        return 1.0 / (1.0 + np.exp(-(X[:, 0] - self.threshold) * self.sharpness))

n = 120X = np.linspace(0.0, 1.0, n).reshape(-1, 1)y = (X[:, 0] >= 0.7).astype(float)w = np.where(y == 1.0, 4.0, 1.0)t0 = np.arange(n)t1 = t0 + 3
grid = ht.expand_param_grid({"threshold": [0.5, 0.7, 0.9], "sharpness": [4.0, 8.0]})best = ht.purged_search(Threshold, grid, X, y, t0, t1, n_splits=4, pct_embargo=0.02, sample_weight=w)print(len(grid), "candidates; best", best["best_params"], round(best["best_score"], 4))
space = {"threshold": ("uniform", 0.45, 0.85), "sharpness": ("log_uniform", 0.1, 20.0)}draws = ht.sample_param_sets(space, n_iter=12, seed=42)print(len(draws), "draws, reproducible:", draws == ht.sample_param_sets(space, n_iter=12, seed=42))
# Test-fold weights count in the score: the weighted log loss of three predictions.print(round(ht.classification_score([1, 0, 1], [0.8, 0.3, 0.4], [2.0, 1.0, 1.0]), 4))
6 candidates; best {'sharpness': 8.0, 'threshold': 0.7} -0.207612 draws, reproducible: True-0.4298With scikit-learn, the purged splits can also go straight into its own search, as long as unweighted scoring is acceptable:
from sklearn.model_selection import GridSearchCVfrom openquant.cross_validation import purged_kfold_splits
splits = purged_kfold_splits(t0, t1, n_splits=5, pct_embargo=0.01)search = GridSearchCV(model, {"C": [0.01, 0.1, 1.0]}, cv=splits, scoring="neg_log_loss")search.fit(X, y, sample_weight=w)  # weights reach fit, not the score
What to watch for
Section titled “What to watch for”- The search does not refit.
SearchResultholds parameters and scores, not a model. Build and fit the winner yourself, on the training span. - Ties go to the last trial, as the accuracy search shows. Order the grid so that the
simplest or most conservative configuration comes last if you want ties broken that way.
A
NaNmean score is treated as equal to everything, so checktrialswhen a model can fail to fit. - Every trial is a trial. The best of 200 configurations looks good partly because it is
the best of 200.
trials.len()is the number to carry into a deflated Sharpe ratio or any other multiple-testing correction — and that includes searches you ran and discarded. - The winner’s score is not an out-of-sample estimate. It was selected for being high. Hold out a final span that the search never sees, or nest the search inside an outer purged loop.
- The embargo starts where the purge ends, after each test fold only (Snippet 7.3), so
pct_embargoremoves that many samples beyond the purge; seecross-validation. - Labels must be 0 or 1 and probabilities finite and in ; anything else is a
TuningError, as are negative weights and a fold left empty by purging.
Related modules
Section titled “Related modules”cross-validation— the splitter and the classifier trait.sample-weights— the weights scored with here.bet-sizing— why calibrated probabilities are worth tuning for.backtest-statistics— deflating results by the number of trials.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.hyperparameter_tuning.
hyperparameter_tuning.expand_param_grid— Every combination of a grid of int, float or bool values, keys in sorted order.hyperparameter_tuning.sample_param_sets— ``n_iter`` random draws from ``param_space``, seeded, as the Rust ``randomized_search``.hyperparameter_tuning.classification_score— Score probabilities of ``y == 1`` against 0/1 labels, weighting samples.hyperparameter_tuning.purged_search— Cross-validate each parameter set on purged folds and pick the best mean score.
Rustdoc for this commit, with every public item of openquant::hyperparameter_tuning (after a crates.io release the same pages are on docs.rs):