
data
Concept Overview
Section titled “Concept Overview”Before any AFML workflow begins, raw market data must be fetched, loaded into a consistent schema, cleaned of duplicates and formatting issues, and aligned to a regular time grid. This module handles that ingestion layer.
fetch(symbols, start, end, source=..., cache_dir=...) gets daily OHLCV bars from a pluggable source. The source is any object with a name and a fetch_symbol(symbol, start, end) method (the DataSource protocol). Three sources ship with the module. LocalSampleSource reads the bundled synthetic sample and is the default. LocalFileSource reads your own CSV or Parquet file. CallableSource wraps your own function, which calls your vendor with your key. Each (source, symbol, date range) request is cached as a Parquet file and a JSON sidecar under <cache_dir>/<source>[@<version>]/<symbol>/<start>_<end>.parquet. A repeated request is served from disk without calling the source, so it works offline, and offline=True makes that a guarantee. The returned frame is the canonical clean_ohlcv frame, and it has passed data_quality_report.
dataset_hash(df) is a deterministic SHA-256 of a table’s contents. record_dataset_hash(manifest, df, **meta) writes that hash, with the source, terms and request, into a run manifest, so every result can name the exact data behind it. experiments/run_pipeline.py records it in every run_manifest.json.
The loaders accept CSV or Parquet files with flexible column naming (e.g., “timestamp”, “datetime”, “date” all map to “ts”; “ticker” or “asset” map to “symbol”) and produce a standardized Polars DataFrame with canonical OHLCV columns. Deduplication handles duplicate (symbol, timestamp) keys, and calendar alignment generates a regular grid with explicit gap markers.
The data quality report provides diagnostics — row counts, symbol counts, duplicate counts, gap intervals, and null counts — that should be inspected before feeding data into bars, labeling, or any downstream module.
When to Use
Section titled “When to Use”For preprocessing directly in Rust through row, column and Polars DataFrame interfaces,
see data_processing. That page covers the exact
UTC timestamp schema, duplicate policy, gap diagnostics and off-grid alignment report.
Use fetch when a study needs daily bars for a list of symbols and must be reproducible. Record the dataset hash in the run manifest. Use the loaders directly when you already hold pre-aggregated OHLCV data (daily bars, minute bars from a vendor). If you have raw tick/trade data instead, use the data_structures module to construct bars first.
Prerequisites: For fetch, a source: the bundled synthetic sample, your own file, or your own vendor function and key. For the loaders, a CSV or Parquet file, or an existing Polars DataFrame with OHLCV-like columns.
Alternatives: Direct Polars/pandas loading if you handle column normalization and cleaning yourself.
Key Parameters
Section titled “Key Parameters”| Parameter | Type | Description | Default |
|---|---|---|---|
symbols | str | Iterable[str] | Symbols to fetch; duplicates are dropped | — |
start, end | date | datetime | str | Inclusive date range (ISO strings accepted) | — |
source | DataSource | None | Where bars come from; None uses the synthetic LocalSampleSource | None |
cache_dir | str | Path | None | Cache root; None uses XDG_CACHE_HOME/openquant/data or ~/.cache/openquant/data | None |
refresh / offline | bool | Refetch even if cached / never call the source (raise CacheMissError) | False |
return_meta | bool | Also return provenance (source, terms, cache status, dataset_hash) for the run manifest | False |
path | str | Path | File path to CSV or Parquet OHLCV data (load_ohlcv) | — |
symbol | str | None | Symbol name if not present as a column in the data | None |
interval | str | Calendar alignment interval (e.g., ‘1d’, ‘1h’, ‘5m’) | ‘1d’ |
dedupe_keep | str | Which duplicate to keep: ‘first’ or ‘last’ | ‘last’ |
Usage Examples
Section titled “Usage Examples”All examples run without credentials or network access. Temporary directories keep each example independent and remove the cache and fixtures afterwards.
Fetch synthetic data, reuse the cache, and record provenance
Section titled “Fetch synthetic data, reuse the cache, and record provenance”from tempfile import TemporaryDirectoryfrom openquant.data import ( fetch, data_quality_report, quality_failures, record_dataset_hash,)
with TemporaryDirectory() as cache: # Bundled SYNTHETIC bars, not real tickers or market observations. df, meta = fetch(["SYN_A", "SYN_B"], "2023-01-01", "2023-03-31", cache_dir=cache, return_meta=True) again, cached = fetch(["SYN_A", "SYN_B"], "2023-01-01", "2023-03-31", cache_dir=cache, return_meta=True, offline=True) assert again.equals(df) assert quality_failures(data_quality_report(df)) == [] manifest = record_dataset_hash({"run_name": "demo"}, df, **meta) assert manifest["dataset_hash"] == cached["dataset_hash"] print(df.columns) print(df.height, meta["cache"]) print(cached["cache"]) print(manifest["dataset_hash"].startswith("sha256:"))['ts', 'symbol', 'open', 'high', 'low', 'close', 'volume', 'adj_close']130 {'SYN_A': 'miss', 'SYN_B': 'miss'}{'SYN_A': 'hit', 'SYN_B': 'hit'}TrueThe source defaults to LocalSampleSource; populating this cache already works
without a network. offline=True is stronger: it prohibits calling any source
and raises CacheMissError when an exact request has no usable cache entry.
Adapt a callable source and demonstrate a cache miss
Section titled “Adapt a callable source and demonstrate a cache miss”A source callable receives (symbol, start, end), with dates inclusive. This
fixture supplies the same interface a vendor adapter would implement, using
only local synthetic rows. A vendor adapter can replace the function body;
its data access and storage terms remain the caller’s responsibility.
from tempfile import TemporaryDirectoryimport polars as plfrom openquant.data import CallableSource, CacheMissError, fetch
calls = []def local_bars(symbol, start, end):    calls.append(symbol)    return pl.DataFrame({        "date": ["2024-01-02", "2024-01-03"],        "open": [100.0, 101.0], "high": [102.0, 103.0],        "low": [99.0, 100.0], "close": [101.0, 102.0],        "volume": [10.0, 12.0],    })
source = CallableSource(local_bars, name="docs-synthetic", version="1",                        terms="Synthetic example generated in this snippet")with TemporaryDirectory() as cache:    request = dict(source=source, cache_dir=cache, return_meta=True)    df, first = fetch("DEMO", "2024-01-02", "2024-01-03", **request)    _, second = fetch("DEMO", "2024-01-02", "2024-01-03", offline=True, **request)    print(df.height, calls, first["cache"], second["cache"])    # A sub-range has a different cache key.    try:        fetch("DEMO", "2024-01-02", "2024-01-02", offline=True, **request)    except CacheMissError:        print("uncached range rejected")
2 ['DEMO'] {'DEMO': 'miss'} {'DEMO': 'hit'}uncached range rejectedCreate a CSV, clean duplicates, and expose a calendar gap
Section titled “Create a CSV, clean duplicates, and expose a calendar gap”from pathlib import Pathfrom tempfile import TemporaryDirectoryimport polars as plfrom openquant.data import load_ohlcv, data_quality_report, align_calendar, dataset_hash
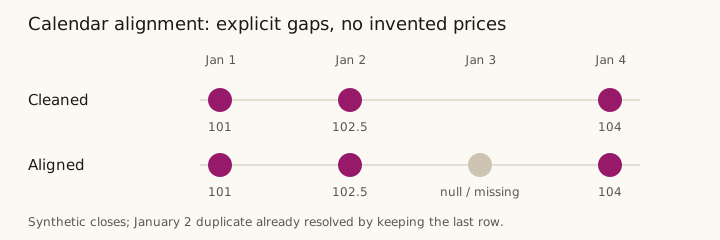
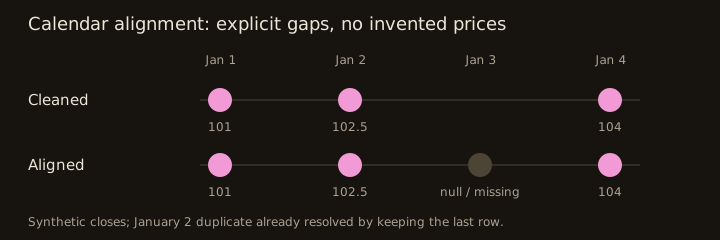
raw = pl.DataFrame({ "date": ["2024-01-01", "2024-01-02", "2024-01-02", "2024-01-04"], "ticker": ["DEMO"] * 4, "open": [100.0, 101.0, 101.0, 103.0], "high": [102.0, 103.0, 103.0, 105.0], "low": [99.0, 100.0, 100.0, 102.0], "close": [101.0, 102.0, 102.5, 104.0], "volume": [10.0, 12.0, 13.0, 14.0],})with TemporaryDirectory() as directory: path = Path(directory) / "prices.csv" raw.write_csv(path) clean, report = load_ohlcv(path, return_report=True) aligned = align_calendar(clean, interval="1d") missing = aligned.filter(pl.col("is_missing_bar")) print(clean.height, report["rows_removed_by_deduplication"]) print(clean["close"].to_list()) print(data_quality_report(clean)["gap_interval_count"]) print(aligned.height, missing["ts"].dt.strftime("%Y-%m-%d").to_list()) print(dataset_hash(clean) == dataset_hash(clean.reverse()))3 1[101.0, 102.5, 104.0]14 ['2024-01-03']TrueThe default duplicate policy keeps the last row, so January 2 closes at 102.5.
Alignment inserts January 3 with null price/volume fields and
is_missing_bar=True; it does not invent a tradable bar or impute prices.
The inferred spacing here is one day (the smallest spacing wins a frequency
tie). The missing weekday is therefore counted as a gap.
Cleaning and provenance contracts
Section titled “Cleaning and provenance contracts”clean_ohlcv produces columns ts, symbol, open, high, low, close, volume, adj_close, ordered by symbol and timestamp. It drops extra columns and rows
with null canonical fields, including unparseable timestamps; a missing
adj_close column is copied from close. The return_report=True cleaning
report retains input null counts even though those rows are removed. Run
data_quality_report(cleaned) separately to describe only the resulting frame.
These behaviors are implemented in
data.py
and exercised in the data tests.
quality_failures requires at least one row, no duplicate keys, and no nulls.
It does not reject gaps or validate price economics (for example, a negative
price or high below low). Passing it means this structural quality bar passed,
not that the data are suitable for a particular study.
The content hash sorts column names and rows, preserving duplicates, and hashes
a canonical typed representation. It intentionally ignores input row/column
order and Parquet layout; integer widths map to one integer kind, floating
widths to Float64, and datetimes to microseconds. A hash identifies this
normalized content, not file bytes, source authenticity or permission to use it.
record_dataset_hash mutates and returns the supplied manifest, recording the
hash version, row count and any source metadata supplied by the caller.
Common Pitfalls
Section titled “Common Pitfalls”- Treating the bundled sample as market data. It is synthetic, so any result computed on it says nothing about real markets.
- Committing cached data without checking the source terms; the bundled sample and externally fetched data have different provenance.
- Expecting a cached range to serve a sub-range. The cache key is the exact (source, symbol, start, end), so a different range is a new fetch.
- Forgetting to check the quality report for gaps — missing bars silently create NaN features downstream.
- Using align_calendar with an interval shorter than the data’s actual frequency — this creates many synthetic missing-bar rows.
- Using align_calendar with bars that are not on the grid. Each symbol’s grid starts at its first bar and steps by
interval, so a bar stamped off that grid (a daily bar at a different time of day, an irregular intraday print) is not in the output.align_calendar(df, interval=..., return_report=True)returns(aligned, report)with those bars inreport["off_grid_bars"]and their number inreport["off_grid_bar_count"]; withoutreturn_reportaUserWarningsays how many were dropped. The_core.data.align_calendarandalign_calendar_dfbindings take the samereturn_reportflag.
Risk Notes and Caveats
Section titled “Risk Notes and Caveats”- The bundled sample is SYNTHETIC, not market data. Its symbols (SYN_A … SYN_E) are not real tickers. DATA_SOURCES.md at the repository root records the terms of every source and why no real sample is committed yet.
- Check your source terms before persisting or redistributing fetched data. See DATA_SOURCES.md for repository data provenance.
dataset_hash(oq-dataset-sha256-v1) describes normalized content, as detailed above. Record source metadata alongside it rather than treating the digest as complete provenance.- Column aliases are resolved automatically (e.g., ‘timestamp’ → ‘ts’, ‘ticker’ → ‘symbol’).
- clean_ohlcv deduplicates by (symbol, ts) and sorts chronologically.
- align_calendar marks missing bars with is_missing_bar=True for downstream imputation logic.
gap_interval_countin the quality report depends on the bar spacing, which the report infers and returns asinferred_interval_us: the most common spacing between consecutive bars of one symbol, pooled over symbols (the smallest on a tie). For daily data (a spacing within an hour of one day) a gap is a skipped weekday, so weekends are not gaps; exchange holidays are, since no holiday calendar is applied. For any other spacing a gap is a spacing longer than the inferred one, so intraday data counts every overnight and weekend break as a gap. Before #168 any spacing over one day was a gap whatever the frequency: weekends counted on daily data, and nothing counted on intraday data.
Sources
Section titled “Sources”- Python implementation: schemas, quality checks, source protocol, caching and content hash specification.
- Data module tests: normalization, duplicate policy, calendar gaps and off-grid reporting.
- Fetch tests: offline cache behavior, source versions and hash provenance.
- Rust data processing:
clean_ohlcv_df,quality_report_dfandalign_calendar_df. Fetch adapters and manifests are Python conveniences, not Rust APIs.
Related Modules
Section titled “Related Modules”API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.data.
data.fetch— Fetch daily OHLCV bars for ``symbols`` over ``[start, end]`` through a local cache.data.dataset_hash— Deterministic content hash of a table, as ``"sha256:<64 hex>"``.data.record_dataset_hash— Record a dataset's content hash, and its provenance, in a run manifest.data.quality_failures— Reasons a :func:`data_quality_report` fails ``fetch``'s bar; empty when it passes.data.default_cache_dir— ``$OPENQUANT_DATA_CACHE``, else ``$XDG_CACHE_HOME/openquant/data``, else ``~/.cache/openquant/data``.data.DataSource— What ``fetch`` needs from a market data source.data.LocalSampleSource— The SYNTHETIC daily OHLCV sample shipped with openquant.data.LocalFileSource— A source backed by one local CSV/Parquet OHLCV file with a ``symbol`` column.data.CallableSource— Adapt a function ``fn(symbol, start, end) -> frame`` into a ``DataSource``.data.CacheMissError— Raised by ``fetch(..., offline=True)`` when a request is not in the cache.data.load_ohlcv— Read an OHLCV CSV or Parquet file and clean it with `clean_ohlcv`.data.clean_ohlcv— Normalize a long OHLCV frame to the canonical schema, sorted and de-duplicated.data.align_calendar— Reindex each symbol onto a regular time grid, marking the bars that are missing.data.data_quality_report— Summarize row counts, duplicate keys, gaps and time range of an OHLCV frame.
Rustdoc for this commit, with every public item of openquant::data_processing (after a crates.io release the same pages are on docs.rs):