
backtesting_engine
A walk-forward backtest is one draw. It tests the strategy on the one sequence of events that happened, in the one order they happened in, and it is easy to tune a strategy until that one draw looks good (AFML §12.2). Chapter 12 sets two alternatives beside it: cross-validation, which asks how the strategy does in each period when trained on all the others, and combinatorial purged cross-validation (CPCV), which recombines the periods to produce many complete out-of-sample paths, and so a distribution of Sharpe ratios rather than a single one.
This module builds the splits for all three, purges and embargoes them, runs a callback you supply on each, and assembles the results. It does not fit models, size positions, or know about prices. From Python, CPCV is available without a callback: see From Python.
How a run is set up
Section titled “How a run is set up”You provide three things.
The data: a BacktestData with one entry per sample and the (start, end) span of each
sample’s label. returns must be the same length and finite, but the engine uses it only to
count samples; performance comes from your callback.
The evaluator: a closure FnMut(&SplitDefinition) -> Result<Vec<f64>, BacktestError>. It
receives train_indices and test_indices, fits whatever you like on the first, and returns
one out-of-sample return per test index, in order.
A run record: BacktestRunConfig holds a free-text mode_provenance, the
trials_count, and five BacktestSafeguards — how the run controls survivorship bias,
look-ahead, data mining, costs and multiple testing (§11.4). Every field must be non-empty or
the run is refused. The engine does not check that what you wrote is true. It makes you write
it down, and returns it with the results in BacktestDiagnostics, where
trials_count is waiting for a
deflated Sharpe ratio.
The three modes
Section titled “The three modes”| Splits | Trains on | Yields | |
|---|---|---|---|
run_walk_forward | a test block of test_size every step_size, after the first min_train_size | everything before the block (expanding window) | one path, over the later part of the sample |
run_cross_validation | n_splits contiguous blocks | everything outside the block | one path, over the whole sample |
run_cpcv | every choice of test_groups out of n_groups blocks | everything outside the chosen blocks | paths, each over the whole sample |
In every mode a training sample is purged if its label span overlaps the span of any test sample, compared pair by pair. That matters for CPCV, where the test set is several disjoint blocks and a single covering window would purge everything in between.
A non-zero pct_embargo then embargoes more training samples after each test block,
where is pct_embargo times the sample count, rounded up (§7.4.2, Snippet 7.3). The count
starts where the purge ends, at the first sample whose label starts after the block’s last
label has ended, so the embargo removes samples the purge kept (fewer than only at the
end of the data or where the next test block begins). Samples before a test block are never
embargoed: their features cannot contain prices from the test window. In CPCV, adjacent test
groups form one block. SplitDefinition::purged_count and embargo_count count the two
removals separately.
Combinatorial purged cross-validation
Section titled “Combinatorial purged cross-validation”Split observations into contiguous groups and test on of them at a time. There are splits, each group is tested in of them, and those test results can be arranged into
complete paths. With and : 15 splits, each group tested 5 times, 5 paths.
cpcv_path_count(n_groups, test_groups) returns .
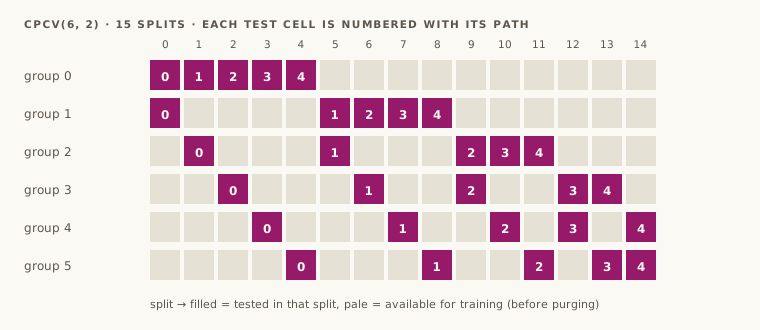
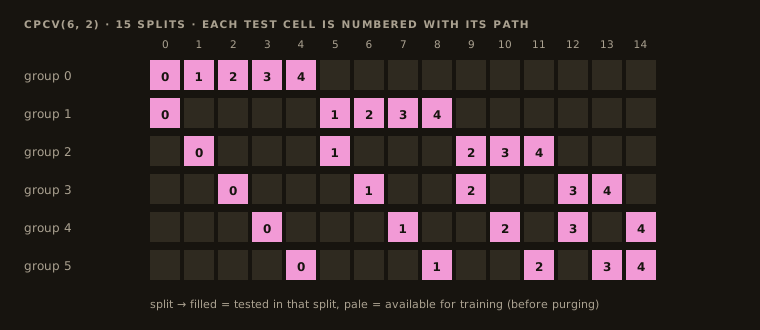
CpcvResult::path_assignments records that mapping and path_distribution holds each path’s
mean, deviation and sharpe.
The example trades a return series with some momentum. Its “model” chooses between a 1-bar and a 10-bar lookback by whichever earned more on the training rows, so what is traded in a test block depends on the training set, as it would with a fitted model.
use chrono::{Duration, NaiveDate};use openquant::backtesting_engine::{    cpcv_path_count, run_cpcv, run_walk_forward, BacktestData, BacktestError, BacktestRunConfig,    BacktestSafeguards, CpcvConfig, SplitDefinition, WalkForwardConfig,};
// Reproducible noise in [-1, 1) from a hash, so the example needs no RNG.fn noise(i: usize, salt: u64) -> f64 {    let mut h = (i as u64).wrapping_mul(0x9E37_79B9_7F4A_7C15) ^ salt.wrapping_mul(0xD1B5_4A32_D192_ED03);    h ^= h >> 31;    h = h.wrapping_mul(0x7FB5_D329_728E_A185);    h ^= h >> 27;    (h >> 11) as f64 / (1u64 << 53) as f64 * 2.0 - 1.0}
// 240 daily returns, each carrying over a quarter of the one before. Labels span 5 days.let n = 240;let mut asset = vec![0.0; n];for i in 1..n {    asset[i] = 0.25 * asset[i - 1] + 0.01 * noise(i, 5);}let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 0, 0).unwrap();let label_spans: Vec<_> =    (0..n as i64).map(|i| (open + Duration::days(i), open + Duration::days(i + 4))).collect();let data = BacktestData { returns: asset.clone(), label_spans };
let note = |s: &str| s.to_string();let run = BacktestRunConfig {    mode_provenance: note("docs example: one rule family, fixed before the run"),    trials_count: 1,    safeguards: BacktestSafeguards {        survivorship_bias_control: note("synthetic single series"),        look_ahead_control: note("lookback chosen on training rows only"),        data_mining_control: note("two candidate lookbacks, declared in advance"),        cost_assumption: note("none modelled"),        multiple_testing_control: note("single trial"),    },};
// Follow the sign of the last `lookback` returns.let rule = |lookback: usize, i: usize| -> f64 {    if i < lookback {        return 0.0;    }    asset[i - lookback..i].iter().sum::<f64>().signum() * asset[i]};let evaluator = |split: &SplitDefinition| -> Result<Vec<f64>, BacktestError> {    let earned = |l: usize| split.train_indices.iter().map(|&i| rule(l, i)).sum::<f64>();    let chosen = if earned(1) >= earned(10) { 1 } else { 10 };    Ok(split.test_indices.iter().map(|&i| rule(chosen, i)).collect())};
let walk = run_walk_forward(    &data,    &run,    &WalkForwardConfig { min_train_size: 80, test_size: 40, step_size: 40, pct_embargo: 0.0 },    evaluator,)?;assert_eq!(walk.folds.len(), 4); // one path, covering only samples 80-239
let cpcv = run_cpcv(    &data,    &run,    &CpcvConfig { n_groups: 6, test_groups: 2, pct_embargo: 0.0 },    evaluator,)?;assert_eq!((cpcv.splits.len(), cpcv.path_count), (15, cpcv_path_count(6, 2)?));assert_eq!(cpcv.path_count, 5);assert!(cpcv.path_distribution.iter().all(|p| p.observations == 240));// Path 0 takes groups 0 and 1 from split 0, then one group from each of splits 1 to 4.assert_eq!(cpcv.path_assignments[0].split_for_group, vec![0, 0, 1, 2, 3, 4]);
// Two adjacent test groups at the start have one boundary with the training set: 4 purged.// Two separated interior groups have four: 16 purged.assert_eq!((cpcv.splits[0].test_groups.clone(), cpcv.splits[0].purged_count), (vec![0, 1], 4));assert_eq!((cpcv.splits[7].test_groups.clone(), cpcv.splits[7].purged_count), (vec![1, 4], 16));
let t_stats: Vec<f64> = cpcv.path_distribution.iter().map(|p| p.sharpe).collect();let (low, high) = (t_stats.iter().cloned().fold(f64::MAX, f64::min), t_stats.iter().cloned().fold(f64::MIN, f64::max));assert!((low - 2.40).abs() < 0.01 && (high - 3.20).abs() < 0.01);
walk-forward fold t-stats +1.88 +1.97 -0.18 +0.67 (160 of 240 samples tested)cpcv(6, 2) path t-stats +2.65 +2.40 +3.20 +3.20 +3.20 (240 samples each)Walk-forward gives four numbers about four 40-day windows and says nothing about the first 80 days. CPCV gives five full-length paths, and the statement “between 2.4 and 3.2” is one about the strategy rather than about a window. Three paths coincide here because the model has only two states; with a real learner they differ.
From Python
Section titled “From Python”A Python model cannot be the evaluator without handing a Python callable to Rust, so
openquant.backtesting_engine turns the callback inside out. Get the splits from
cross_validation.cpcv_splits, fit and trade each
one in Python, and pass the out-of-sample returns in: split_returns[s] holds one return per
index of split s’s test_indices, in order. run_cpcv then runs the Rust run_cpcv with a
closure that hands back your returns, and returns its result as a dict: folds, splits,
path_count, path_assignments, path_distribution and diagnostics. The run record is
required here too, as keyword arguments. assemble_cpcv_paths stitches any per-split values
(returns, predictions, positions) into an (n_paths, n_samples) array, for statistics the
engine does not compute, such as a deflated Sharpe ratio per
path.
import numpy as npfrom openquant import backtesting_engine as btfrom openquant import cross_validation as cv
# 60 daily labels, each resolved 2 days later; 6 groups, tested 2 at a time.t0 = np.datetime64("2024-01-01") + np.arange(60) * np.timedelta64(1, "D")t1 = t0 + np.timedelta64(2, "D")splits = cv.cpcv_splits(t0, t1, n_splits=6, n_test_splits=2, pct_embargo=0.02)
# Stand-in for "fit on train_indices, trade test_indices": the market's return per sample,# plus a per-split difference, since each split's model is trained on different data.rng = np.random.default_rng(0)market = rng.normal(0.001, 0.01, size=60)split_returns = [market[s["test_indices"]] + rng.normal(0, 0.002, len(s["test_indices"])) for s in splits]
result = bt.run_cpcv(    t0, t1, split_returns,    n_groups=6, test_groups=2, pct_embargo=0.02,    mode_provenance="docs example", trials_count=1,    safeguards={        "survivorship_bias_control": "synthetic data",        "look_ahead_control": "synthetic data",        "data_mining_control": "one configuration",        "cost_assumption": "none",        "multiple_testing_control": "trials_count = 1",    },)print(result["path_count"], "paths from", len(result["splits"]), "splits")for path in result["path_distribution"]:    print(path["path_id"], path["observations"], round(path["mean_return"], 6))
paths = bt.assemble_cpcv_paths(split_returns, splits, cv.cpcv_paths(6, 2))print(paths.shape, np.round(paths.mean(axis=1), 6).tolist())
5 paths from 15 splits0 60 0.0019021 60 0.001632 60 0.0018693 60 0.0012894 60 0.001633(5, 60) [0.001902, 0.00163, 0.001869, 0.001289, 0.001633]Both modules test the same samples in the same split order, and the engine’s
path_assignments equal cross_validation.cpcv_paths. With increasing label starts the
training sets match too: the two modules share the embargo code, and purging each block
against its whole window, as cross_validation does, removes the same samples as the engine’s
pair-by-pair purge. The engine’s own training sets appear in result["splits"] as a record
only; the model was trained on the ones you used. Walk-forward and purged-CV modes are
not bound; purged k-fold splits come from cross_validation.purged_kfold_splits.
What to watch for
Section titled “What to watch for”sharpeis a t-statistic, not an annualised Sharpe ratio. It is with the number of returns in the fold or path, so it grows with sample length and cannot be compared across folds of different sizes. For an annualised figure computemean_return / std_return * sqrt(periods per year)yourself.- CPCV paths are not independent. They are rearrangements of the same 15 sets of predictions and share most of their returns. The spread across paths understates the true uncertainty; it is a lower bound on how fragile the result is, not a confidence interval.
- In walk-forward mode the embargo removes nothing. Training data lies entirely before
the test block, and only samples after a block are embargoed, so
pct_embargohas no effect there. If you want a gap between training and test in walk-forward, leave it out oftrain_indicesin your evaluator. Before #94 the embargo was applied on both sides of every test sample, counted from the block’s edge rather than from the end of the purge. - Your evaluator must return one value per test index, in order. A different length is an error in CPCV and goes unnoticed in the other two modes, where returns are only summarised.
- Walk-forward windows can overlap or leave gaps.
step_sizebelowtest_sizetests some samples twice; above it, some are never tested. Set them equal unless you mean it. - Cost grows quickly. Purging compares every training span with every test span, and
CPCV runs splits:
(10, 2)is 45 model fits,(16, 8)is 12,870. On tens of thousands of samples the purge alone is billions of comparisons. - The safeguards are a record, not a control. A non-empty string passes. What makes them useful is that they travel with the result.
Related modules
Section titled “Related modules”cross-validation—PurgedKFold, the single-path splitter, and the classifier trait.backtest-statistics— PSR and DSR for the returns and trial count produced here.synthetic-backtesting— the third alternative to walk-forward: simulate the process instead of resampling history.labeling— where label spans come from.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.backtesting_engine.
backtesting_engine.cpcv_path_count— φ[N, k] = k/N · C(N, k), the number of backtest paths CPCV produces (AFML §12.4).backtesting_engine.run_cpcv— Score precomputed CPCV out-of-sample returns per split and per backtest path.backtesting_engine.assemble_cpcv_paths— Stitch per-split out-of-sample values into full CPCV paths.
Rustdoc for this commit, with every public item of openquant::backtesting_engine (after a crates.io release the same pages are on docs.rs):