
sample_weights
sampling measures how much each label overlaps its neighbours. This
module turns that into the sample_weight a classifier is fitted with, in two ways that
answer different questions. Return attribution asks how much happened during a label and
how much of it the label can claim for itself. Time decay asks how old the label is. They
are independent, and AFML’s suggestion (§4.7) is to multiply them.
Unlike sampling, both functions take timestamps: events are (start, end, label) triples
and close is the bar series the labels were built on. The third element of each event is
not used by either function.
Weights by return attribution
Section titled “Weights by return attribution”Two labels that span the same large move are not two pieces of evidence about it. Snippet 4.10 credits each label with the log returns inside its span, each divided by the number of labels alive at that bar, and takes the absolute value of the sum:
where is the concurrency from sampling
and the second step scales the weights to sum to the number of labels , so their mean is 1
and a learning rate tuned on unweighted data still means roughly the same thing.
from datetime import datetime, timedelta
from openquant import sample_weights
start = datetime(2024, 1, 2, 9, 30)stamps = [(start + timedelta(minutes=i)).strftime("%Y-%m-%d %H:%M:%S") for i in range(8)]close = [100.0, 100.5, 101.5, 101.0, 101.2, 101.1, 103.0, 103.2]
# (start, end, label). A and B share bars 1-3, so they split the same move. C stands alone# through a quiet stretch; D stands alone through the largest move of the series.events = [    (stamps[0], stamps[3], 1.0),   # A    (stamps[1], stamps[3], 1.0),   # B    (stamps[4], stamps[5], -1.0),  # C    (stamps[6], stamps[7], 1.0),   # D]by_return = sample_weights.get_weights_by_return(events, stamps, close)by_decay = sample_weights.get_weights_by_time_decay(events, stamps, close, 0.5)for name, (_, r), (_, d) in zip("ABCD", by_return, by_decay):    print(f"{name}  return-attributed {r:.3f}   time-decay {d:.3f}   product {r * d:.3f}")print(f"return-attributed weights sum to {sum(w for _, w in by_return):.1f}")
A return-attributed 0.632 time-decay 0.600 product 0.379B return-attributed 0.632 time-decay 0.680 product 0.430C return-attributed 0.126 time-decay 0.840 product 0.106D return-attributed 2.611 time-decay 1.000 product 2.611return-attributed weights sum to 4.0D carries twenty times the weight of C: the same number of bars, neither overlapping anything, but the price moved 2% during one and 0.1% during the other. A and B each get half of the move they share. That is the method working as designed, and it is also its main hazard — see the first item under What to watch for.
One detail decides the numbers at the edges. Returns are computed once over the whole series
and a label collects every return whose arrival bar lies in [start, end], including the
return that arrives at the event bar itself, which was earned before the event. This follows
Snippet 4.10 exactly. It is why A and B above have identical weights although A starts a bar
earlier: bar 0 is the first bar of the series and has no return to contribute.
Weights by time decay
Section titled “Weights by time decay”Markets adapt, so an old example should count for less than a recent one (§4.7). Snippet 4.11 applies a piecewise-linear decay, but not along the calendar: the horizontal axis is cumulative average uniqueness, with labels in start order. A stretch of heavily overlapping labels advances the clock slowly, so redundant observations do not age each other out.
The newest label always has weight 1. The parameter (decay) sets the other end:
decay | Weight of the oldest label |
|---|---|
1.0 | 1 — no decay |
0 < c < 1 | decays linearly toward |
0.0 | decays linearly toward 0 |
-1 < c < 0 | 0 for the oldest fraction of cumulative uniqueness, then linear up to 1 |
These are AFML’s cases, and decay must lie in : anything else (including NaN)
is rejected with an error (ValueError in Python). A value above 1 would weight old labels
more than new ones, and divides by zero.
With the final cumulative uniqueness, the weight is where for and for , and .
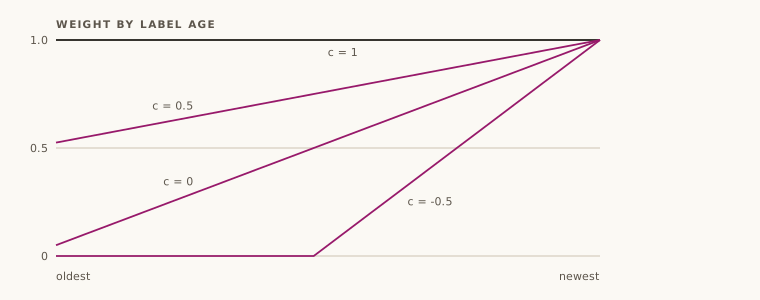
The oldest label’s weight approaches rather than equalling it, because the line is
anchored at and the oldest label already sits at . In the example above
decay=0.5 gives A a weight of 0.600, not 0.500. With thousands of labels the difference
vanishes.
The time-decay weights are not rescaled, and they do not include return attribution. To use both, multiply them as the example does, and rescale the product if your learner is sensitive to the total.
From Rust
Section titled “From Rust”use chrono::{Duration, NaiveDate};use openquant::sample_weights::{get_weights_by_return, get_weights_by_time_decay};
let open = NaiveDate::from_ymd_opt(2024, 1, 2).unwrap().and_hms_opt(9, 30, 0).unwrap();let prices = [100.0, 100.5, 101.5, 101.0, 101.2, 101.1, 103.0, 103.2];let close: Vec<_> = prices.iter().enumerate().map(|(i, p)| (open + Duration::minutes(i as i64), *p)).collect();let at = |i: usize| close[i].0;let events = vec![(at(0), at(3), 1.0), (at(1), at(3), 1.0), (at(4), at(5), -1.0), (at(6), at(7), 1.0)];
let by_return = get_weights_by_return(&events, &close)?;let total: f64 = by_return.iter().map(|(_, w)| w).sum();assert!((total - 4.0).abs() < 1e-9);// The two overlapping labels split one move evenly.assert!((by_return[0].1 - by_return[1].1).abs() < 1e-12);
let by_decay = get_weights_by_time_decay(&events, &close, 0.5)?;assert!((by_decay[3].1 - 1.0).abs() < 1e-12);assert!((by_decay[0].1 - 0.6).abs() < 1e-12);Both return (event start, weight) pairs in the order the events were given.
What to watch for
Section titled “What to watch for”- Return attribution rewards whatever moved, including what you cannot trade. One gap, one bad print or one halted-and-reopened bar can hand a single label most of the total weight, and the normalisation then takes it away from everything else. Look at the largest few weights before fitting, and consider winsorising them. A label over a flat stretch gets a weight near zero and is effectively deleted from training, which is rarely what you want for a meta-label whose correct answer was “do nothing”.
- Events that share a start time are ordered by input position. Both functions return one
weight per event, duplicates included. For time decay, events with the same start take
consecutive places on the cumulative-uniqueness axis in the order you passed them, so the
one listed later counts as newer and, whenever
decay < 1, weighs more. Swapping two such events swaps which one that is; sort them first (by end time, say) if the choice should not depend on input order. Until #91 the duplicates were dropped. - Weights are fitted quantities. Concurrency and cumulative uniqueness are computed over the events you pass. Compute weights on the training fold only; weights computed over the whole history leak the future’s label density into the past.
- Timestamps must match exactly. A label’s span is matched to
closeby comparing timestamps, so an event time that is not a bar time still works. Anendbefore itsstartis rejected withSampleWeightsError::EndBeforeStart, which names the first offending event (aValueErrorfrom Python). From Python, timestamps are"%Y-%m-%d %H:%M:%S"strings with an optional fractional second. - Class imbalance is a separate correction. Neither function looks at the label. AFML
§4.8 handles imbalance with
class_weight='balanced'in the learner, on top of these.
Related modules
Section titled “Related modules”sampling— concurrency, average uniqueness and the sequential bootstrap.labeling— the events and barrier-touch times these functions take.cross-validation— purged folds; compute weights inside them.sb-bagging— the bagging ensemble for overlapping labels. It accepts asample_weightargument but does not use it yet.
API reference
Section titled “API reference”Python
Section titled “Python”Signatures, parameters, return values and errors for every function: openquant.sample_weights.
sample_weights.get_weights_by_return— Sample weights by return attribution (AFML section 4.6, Snippet 4.10).sample_weights.get_weights_by_time_decay— Sample weights by time decay along cumulative uniqueness (AFML section 4.7, Snippet 4.11).
Rustdoc for this commit, with every public item of openquant::sample_weights (after a crates.io release the same pages are on docs.rs):